DATA SCIENCE & COMPUTATIONAL BIOLOGY

Hello, I’m

Shawn
Muhr.

/A data scientist, computational biologist, scientist, and epidemiologist.

I build models for disease prediction and study how cells and biological systems change.

Explore the science
CELL STATES & GENE EXPRESSION
Actual saved Decipher coordinates from the lab tutorial dataset. Color shows source cell annotations or measured gene expression.Decipher · saved model coordinates-2-1012-1.5-0.50.51.5Latent coordinate v₁Latent coordinate v₂Explore the fitted cell-state space →
Decipher · coordinates from the lab’s tutorial dataDataset source ↗
Machine learning · Computational biology · Human healthABOUT ME ↓

WORK, RESEARCH & EDUCATION

01 / ABOUT ME

About me

I’m Shawn, a data scientist working on disease prediction at BranchLab.

I’ve also joined Raghav Sehgal at the Hinda and Arthur Marcus Institute for Aging Research.

My research has included cancer cell differentiation in Columbia’s Azizi Lab and mosquito behavior in the Duvall Lab. At Colorado School of Mines, I supported Alzheimer’s disease research through SNP data extraction and cleaning and research code review.

I earned my M.S. in Data Science and B.S. in Quantitative Biosciences and Engineering at Mines. I also founded the BioBuilders Society and a biosciences outreach program, and taught students through CSM 101 and DECtech.

02 / MY WORK

My work

Research data, model outputs, and methods from the projects I’ve worked on. Select a measurement, gene, or model step to explore.

01 / BRANCHLAB

Disease modeling

01 / DISEASE MODELINGProject method

Disease prediction at BranchLab

At BranchLab, I build disease-prediction models using environmental and population data. One project used a normalized additive piecewise model for outbreaks.

My role: Data Scientist · June 2025–Present

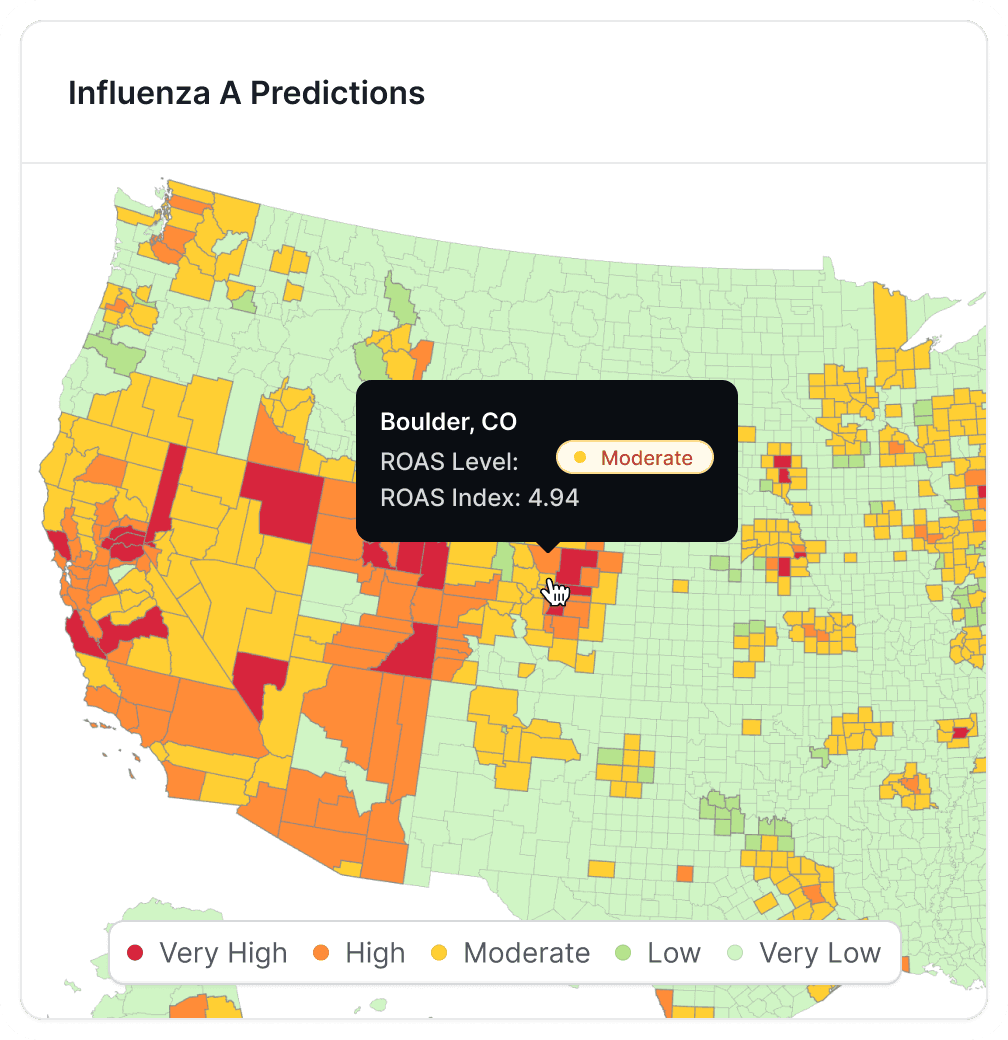
The fixed map is BranchLab’s original public graphic. The model diagram below describes the structure of my outbreak project.

Explore BranchLab
BranchLab’s public Influenza A predictions map, including its Boulder, Colorado tooltip.View full size

BranchLab’s public Influenza A graphic. This is a fixed image, not a live forecast.

© BranchLab · Original source ↗
The outbreak-model structure
My project

Select a stage in the normalized additive piecewise model I worked on at BranchLab.

The outbreak-model structureViral loaddisease signalPopulation densitypopulation contextVaccination ratepopulation contextNormalize inputsx → x̃Piecewise contributionsf₁(x̃₁), f₂(x̃₂), …Additive outputb + Σⱼ fⱼ(x̃ⱼ)
Signals

Viral load, population density, vaccination rates, and other environmental measures enter the model.

x = [viral load, density, vaccination, …]

Normalization

Inputs with different units are normalized before their contributions are combined.

x̃ⱼ = normalize(xⱼ)

Piecewise terms

Each input contributes through a piecewise function. The boundaries and coefficients belong to the fitted model.

fⱼ(x̃ⱼ) = contribution within the relevant interval

Additive output

The model combines the contributions. This diagram describes the structure; it does not substitute invented parameters for the production model.

ŷ = b + Σⱼ fⱼ(x̃ⱼ)

Project structure from my BranchLab experience. The original company map above remains fixed. BranchLab ↗

Lab references & project notes
02 / COLUMBIA UNIVERSITY

Azizi Lab & Duvall Lab

02 / AZIZI LAB · COMPUTATIONAL CANCER BIOLOGYLab work + model extension

Cancer cell states with Decipher

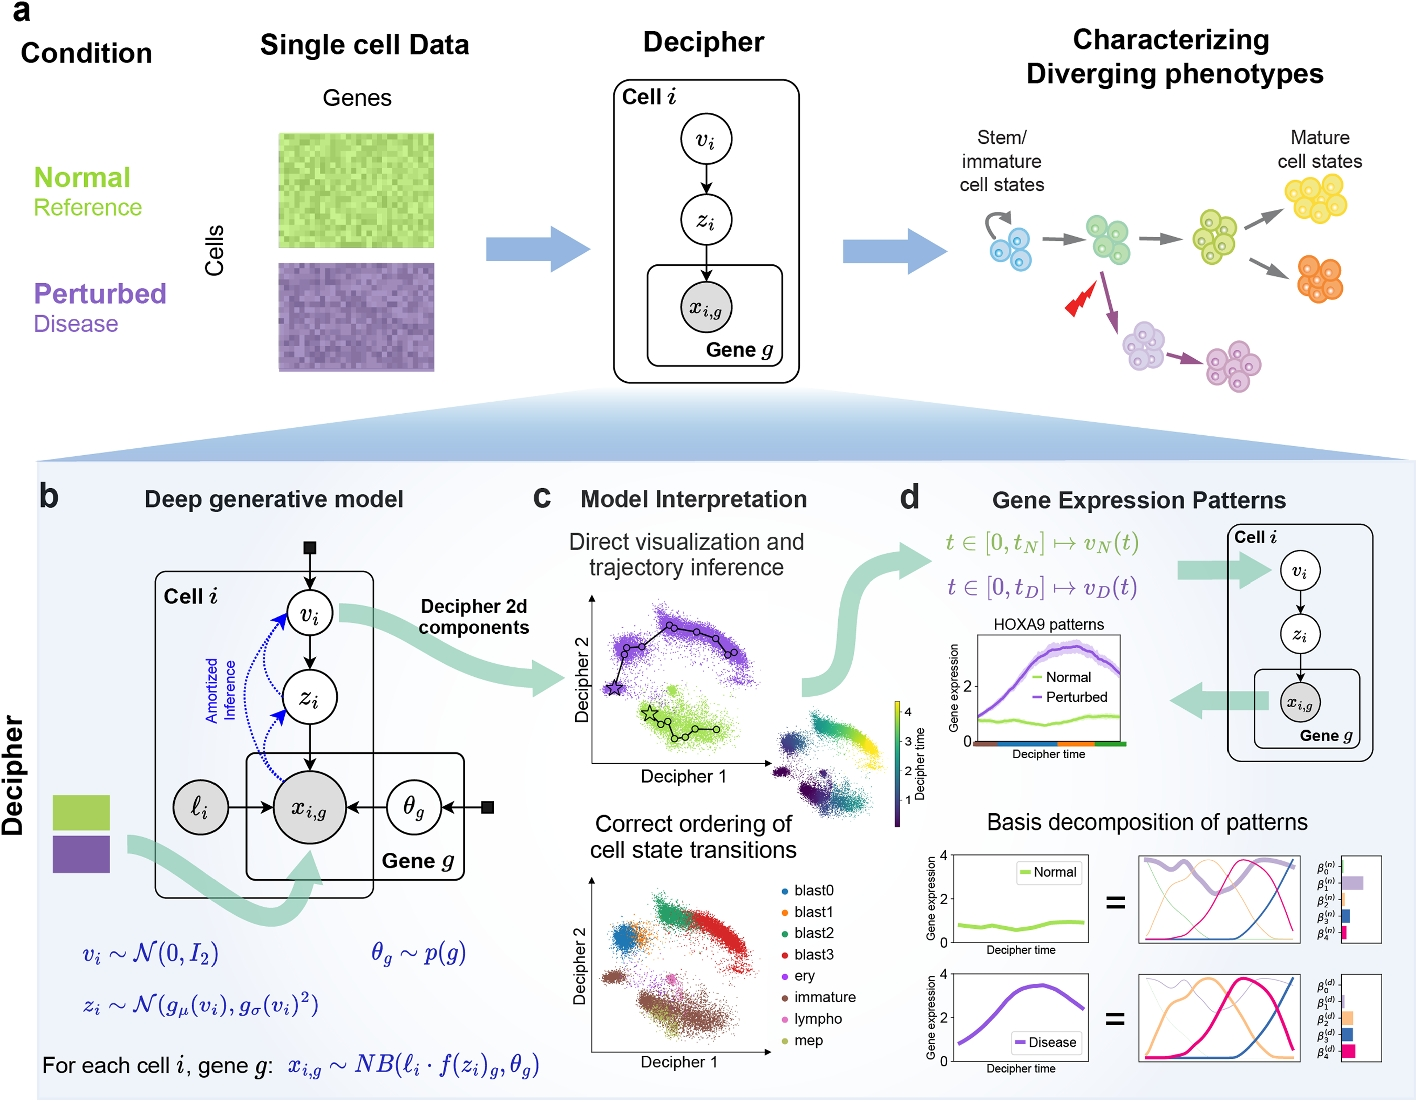
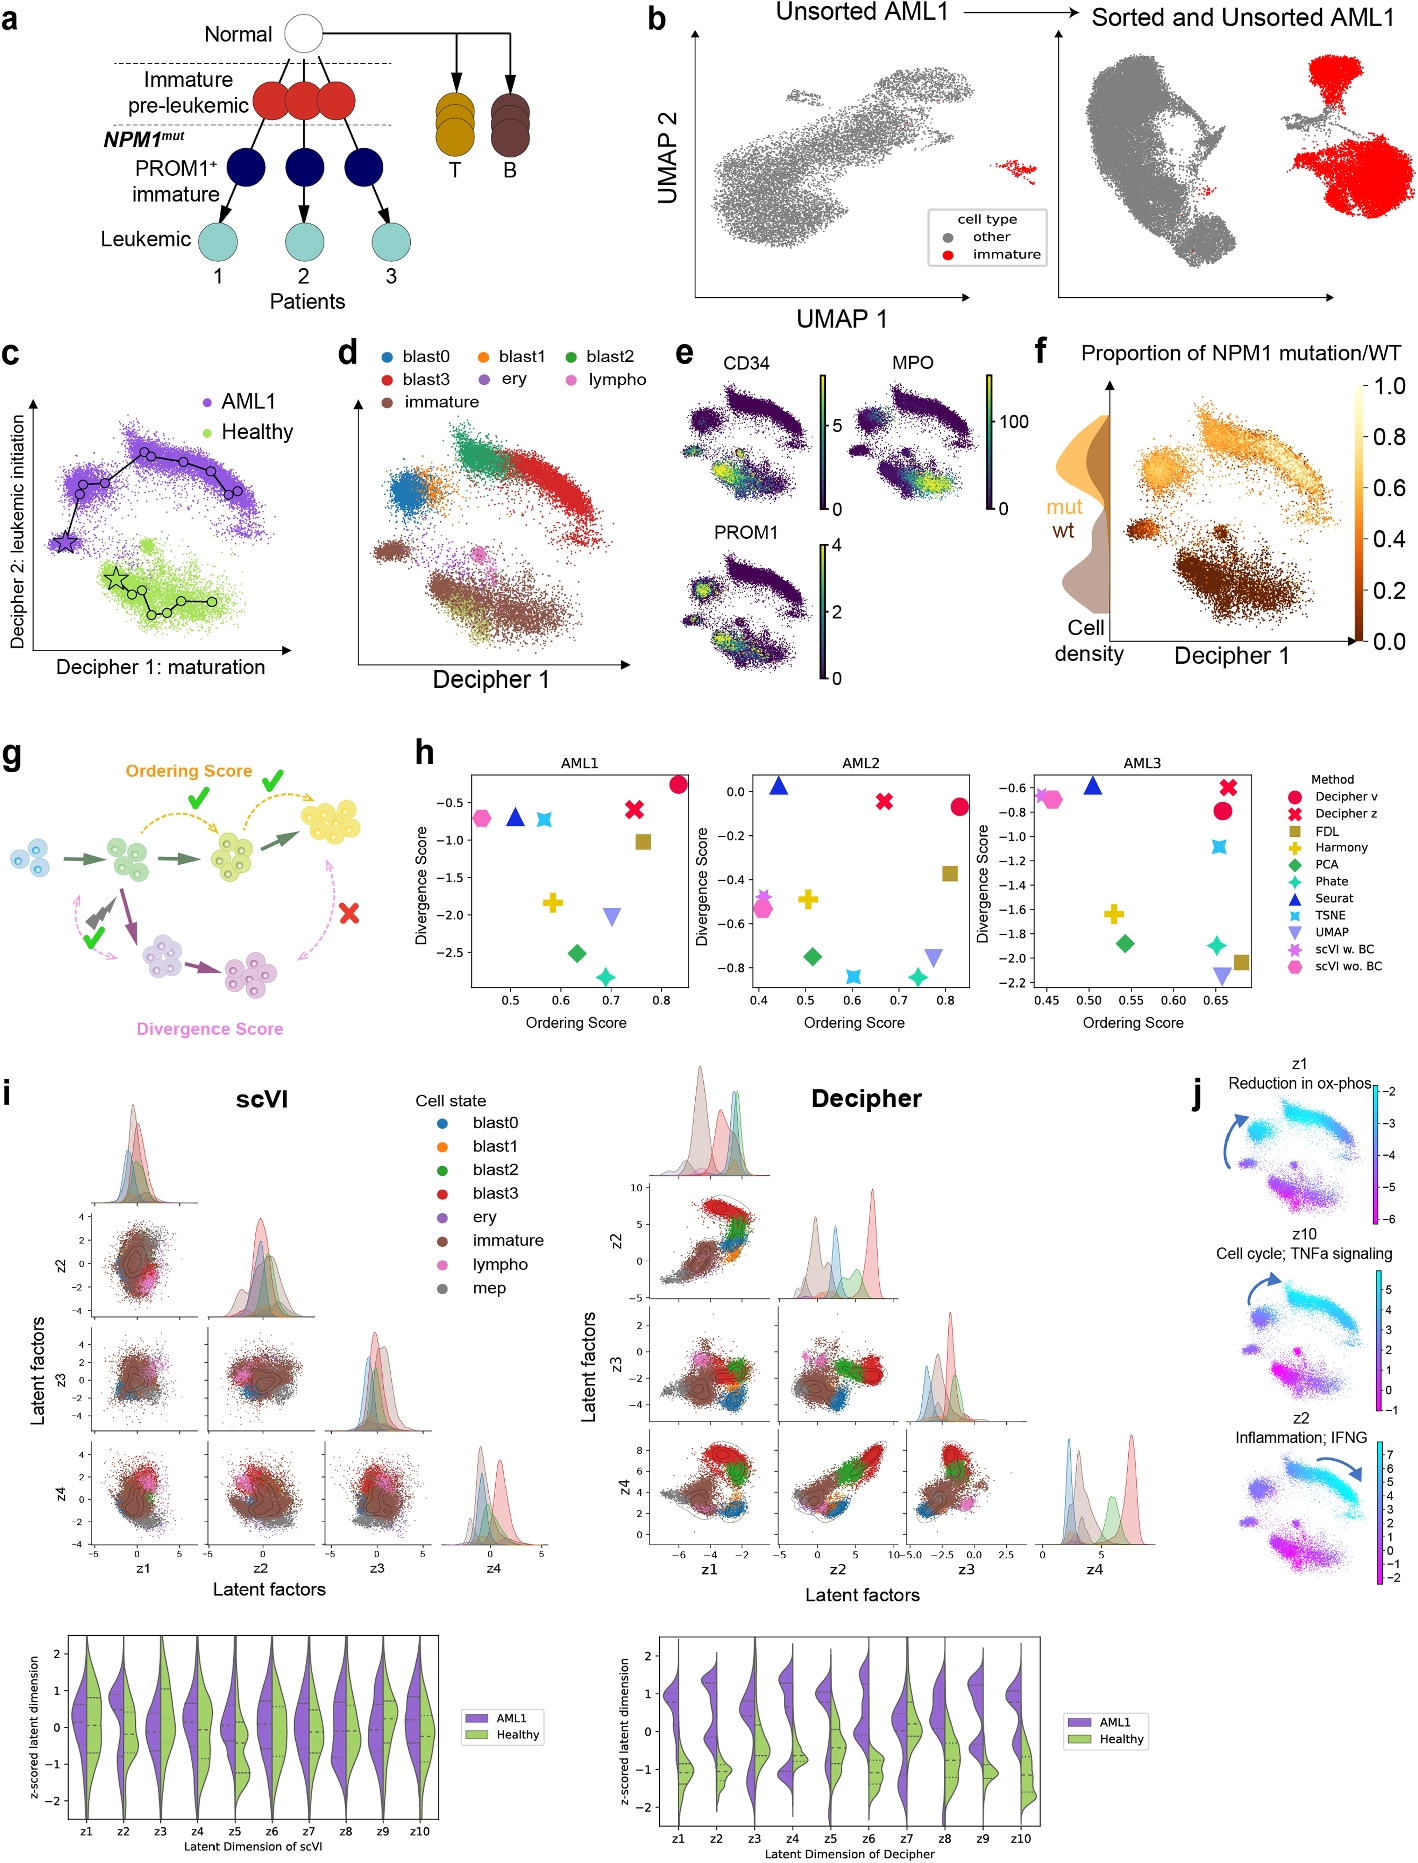
I worked on computational cancer research in the Azizi Lab, contributing to Decipher’s model architecture and visualizations of cell differentiation. My work included adding ATAC-seq information to a Decipher-based model. The walkthrough below follows that extension, with the published Figure 1 available for comparison.

My role: Machine Learning Cancer Researcher · March–December 2024

DECIPHER / MY RNA + ATAC WORK
From RNA and ATAC to shared cell states
Compare with the original ↗

My extension adds chromatin accessibility to the RNA model. Follow paired measurements through the two observation models, inspect fitted cell states, and compare recovery with the RNA-only ablation. The plots use numerical outputs from my local simulation run.

This walkthrough explains the architecture. The trajectory evaluation below tests whether the fitted representations preserve biological structure, separately from these earlier signal-prediction plots.

Swipe diagrams sideways to see the full plot.

1 / 5 · Paired measurements enter the model

The two matrices describe the same simulated cells: RNA counts and binary ATAC accessibility. Selecting a row follows that cell through its latent state and feature profiles.

aRNA and accessibility from the same cellsSynthetic benchmark · numerical model inputs
Paired inputs from the local synthetic run. RNA tiles show log-normalized counts; ATAC tiles show binary accessibility. The selected row follows one cell across both matrices.RNA · 8 of 56 genesATAC · 12 of 120 peakslog(1 + 10,000 × count / library)0 closed · 1 accessible1Cell 1 · gene_0: 0 raw countsCell 1 · gene_1: 8 raw countsCell 1 · gene_2: 5 raw countsCell 1 · gene_3: 3 raw countsCell 1 · gene_4: 20 raw countsCell 1 · gene_5: 1 raw countsCell 1 · gene_6: 12 raw countsCell 1 · gene_7: 1 raw countsCell 1 · peak_0: closedCell 1 · peak_1: accessibleCell 1 · peak_2: closedCell 1 · peak_3: closedCell 1 · peak_4: accessibleCell 1 · peak_5: closedCell 1 · peak_6: closedCell 1 · peak_7: closedCell 1 · peak_8: accessibleCell 1 · peak_9: closedCell 1 · peak_10: closedCell 1 · peak_11: closed2Cell 2 · gene_0: 7 raw countsCell 2 · gene_1: 21 raw countsCell 2 · gene_2: 14 raw countsCell 2 · gene_3: 8 raw countsCell 2 · gene_4: 12 raw countsCell 2 · gene_5: 16 raw countsCell 2 · gene_6: 23 raw countsCell 2 · gene_7: 18 raw countsCell 2 · peak_0: closedCell 2 · peak_1: closedCell 2 · peak_2: closedCell 2 · peak_3: closedCell 2 · peak_4: closedCell 2 · peak_5: accessibleCell 2 · peak_6: closedCell 2 · peak_7: closedCell 2 · peak_8: closedCell 2 · peak_9: accessibleCell 2 · peak_10: closedCell 2 · peak_11: closed3Cell 3 · gene_0: 12 raw countsCell 3 · gene_1: 39 raw countsCell 3 · gene_2: 12 raw countsCell 3 · gene_3: 26 raw countsCell 3 · gene_4: 15 raw countsCell 3 · gene_5: 14 raw countsCell 3 · gene_6: 28 raw countsCell 3 · gene_7: 14 raw countsCell 3 · peak_0: closedCell 3 · peak_1: closedCell 3 · peak_2: accessibleCell 3 · peak_3: accessibleCell 3 · peak_4: closedCell 3 · peak_5: closedCell 3 · peak_6: closedCell 3 · peak_7: accessibleCell 3 · peak_8: closedCell 3 · peak_9: closedCell 3 · peak_10: closedCell 3 · peak_11: accessible4Cell 4 · gene_0: 5 raw countsCell 4 · gene_1: 7 raw countsCell 4 · gene_2: 14 raw countsCell 4 · gene_3: 10 raw countsCell 4 · gene_4: 20 raw countsCell 4 · gene_5: 19 raw countsCell 4 · gene_6: 17 raw countsCell 4 · gene_7: 10 raw countsCell 4 · peak_0: closedCell 4 · peak_1: closedCell 4 · peak_2: closedCell 4 · peak_3: accessibleCell 4 · peak_4: accessibleCell 4 · peak_5: accessibleCell 4 · peak_6: accessibleCell 4 · peak_7: closedCell 4 · peak_8: closedCell 4 · peak_9: closedCell 4 · peak_10: accessibleCell 4 · peak_11: closed5Cell 5 · gene_0: 6 raw countsCell 5 · gene_1: 9 raw countsCell 5 · gene_2: 12 raw countsCell 5 · gene_3: 4 raw countsCell 5 · gene_4: 61 raw countsCell 5 · gene_5: 10 raw countsCell 5 · gene_6: 19 raw countsCell 5 · gene_7: 11 raw countsCell 5 · peak_0: closedCell 5 · peak_1: accessibleCell 5 · peak_2: closedCell 5 · peak_3: closedCell 5 · peak_4: closedCell 5 · peak_5: closedCell 5 · peak_6: closedCell 5 · peak_7: closedCell 5 · peak_8: closedCell 5 · peak_9: closedCell 5 · peak_10: closedCell 5 · peak_11: closed6Cell 6 · gene_0: 26 raw countsCell 6 · gene_1: 12 raw countsCell 6 · gene_2: 22 raw countsCell 6 · gene_3: 7 raw countsCell 6 · gene_4: 17 raw countsCell 6 · gene_5: 26 raw countsCell 6 · gene_6: 24 raw countsCell 6 · gene_7: 16 raw countsCell 6 · peak_0: closedCell 6 · peak_1: closedCell 6 · peak_2: closedCell 6 · peak_3: closedCell 6 · peak_4: accessibleCell 6 · peak_5: accessibleCell 6 · peak_6: accessibleCell 6 · peak_7: closedCell 6 · peak_8: closedCell 6 · peak_9: closedCell 6 · peak_10: closedCell 6 · peak_11: accessible7Cell 7 · gene_0: 34 raw countsCell 7 · gene_1: 8 raw countsCell 7 · gene_2: 11 raw countsCell 7 · gene_3: 30 raw countsCell 7 · gene_4: 1 raw countsCell 7 · gene_5: 23 raw countsCell 7 · gene_6: 2 raw countsCell 7 · gene_7: 34 raw countsCell 7 · peak_0: closedCell 7 · peak_1: closedCell 7 · peak_2: closedCell 7 · peak_3: accessibleCell 7 · peak_4: closedCell 7 · peak_5: closedCell 7 · peak_6: closedCell 7 · peak_7: closedCell 7 · peak_8: closedCell 7 · peak_9: closedCell 7 · peak_10: accessibleCell 7 · peak_11: closed8Cell 8 · gene_0: 4 raw countsCell 8 · gene_1: 17 raw countsCell 8 · gene_2: 13 raw countsCell 8 · gene_3: 9 raw countsCell 8 · gene_4: 23 raw countsCell 8 · gene_5: 6 raw countsCell 8 · gene_6: 22 raw countsCell 8 · gene_7: 25 raw countsCell 8 · peak_0: closedCell 8 · peak_1: accessibleCell 8 · peak_2: closedCell 8 · peak_3: closedCell 8 · peak_4: accessibleCell 8 · peak_5: closedCell 8 · peak_6: closedCell 8 · peak_7: closedCell 8 · peak_8: closedCell 8 · peak_9: closedCell 8 · peak_10: closedCell 8 · peak_11: closed9Cell 9 · gene_0: 2 raw countsCell 9 · gene_1: 10 raw countsCell 9 · gene_2: 3 raw countsCell 9 · gene_3: 0 raw countsCell 9 · gene_4: 31 raw countsCell 9 · gene_5: 3 raw countsCell 9 · gene_6: 5 raw countsCell 9 · gene_7: 4 raw countsCell 9 · peak_0: accessibleCell 9 · peak_1: accessibleCell 9 · peak_2: accessibleCell 9 · peak_3: accessibleCell 9 · peak_4: closedCell 9 · peak_5: closedCell 9 · peak_6: closedCell 9 · peak_7: closedCell 9 · peak_8: accessibleCell 9 · peak_9: closedCell 9 · peak_10: closedCell 9 · peak_11: accessible10Cell 10 · gene_0: 1 raw countsCell 10 · gene_1: 7 raw countsCell 10 · gene_2: 10 raw countsCell 10 · gene_3: 2 raw countsCell 10 · gene_4: 33 raw countsCell 10 · gene_5: 3 raw countsCell 10 · gene_6: 22 raw countsCell 10 · gene_7: 1 raw countsCell 10 · peak_0: closedCell 10 · peak_1: closedCell 10 · peak_2: closedCell 10 · peak_3: closedCell 10 · peak_4: closedCell 10 · peak_5: accessibleCell 10 · peak_6: accessibleCell 10 · peak_7: closedCell 10 · peak_8: accessibleCell 10 · peak_9: closedCell 10 · peak_10: closedCell 10 · peak_11: closed11Cell 11 · gene_0: 16 raw countsCell 11 · gene_1: 21 raw countsCell 11 · gene_2: 13 raw countsCell 11 · gene_3: 15 raw countsCell 11 · gene_4: 11 raw countsCell 11 · gene_5: 5 raw countsCell 11 · gene_6: 12 raw countsCell 11 · gene_7: 10 raw countsCell 11 · peak_0: closedCell 11 · peak_1: closedCell 11 · peak_2: closedCell 11 · peak_3: accessibleCell 11 · peak_4: closedCell 11 · peak_5: accessibleCell 11 · peak_6: closedCell 11 · peak_7: closedCell 11 · peak_8: closedCell 11 · peak_9: closedCell 11 · peak_10: closedCell 11 · peak_11: closed12Cell 12 · gene_0: 11 raw countsCell 12 · gene_1: 12 raw countsCell 12 · gene_2: 15 raw countsCell 12 · gene_3: 6 raw countsCell 12 · gene_4: 9 raw countsCell 12 · gene_5: 5 raw countsCell 12 · gene_6: 23 raw countsCell 12 · gene_7: 10 raw countsCell 12 · peak_0: closedCell 12 · peak_1: closedCell 12 · peak_2: closedCell 12 · peak_3: accessibleCell 12 · peak_4: closedCell 12 · peak_5: closedCell 12 · peak_6: closedCell 12 · peak_7: accessibleCell 12 · peak_8: closedCell 12 · peak_9: accessibleCell 12 · peak_10: closedCell 12 · peak_11: closedg0g1g2g3g4g5g6g7p0p2p4p6p8p10Rows: cells 1–12 of 280Same cell order in both matricesRNA + ATAC evidenceTwo encoders + product of expertsShared cell state6 factors z · 2D coordinates v

Cell 1 · training · 917 RNA counts across 56 genes · 32 of 120 peaks accessible. The tiles display a subset of features; the model uses all features.

bA shared state with two observation models
Generative model: a two-dimensional normal v generates six-dimensional z, which generates negative-binomial RNA counts and Bernoulli peak accessibility.ATAC peaks aBernoullisigmoid(decoder(z))Accessible: 1 · closed: 0v · 2D stateStandard normal priorz · 6 shared factorsGaussian p(z | v)RNA counts xNegative binomialℓ × softmax(decoder(z))Gene dispersion θBoth observation terms active

This is the generative direction. During inference, separate encoders combine RNA and ATAC evidence into z and infer v. RNA library size ℓ and gene dispersion θ enter the count model. This fit normalizes the RNA encoder input and uses 25% modality dropout during training. Cell 1 · posterior-mean z: [1.54, -3.46, -0.92, 1.13, -0.98, -0.77].

cThe learned state of each cell

Color follows the known simulated program. The ring locates the selected cell.

Normalization + dropout: fitted two-dimensional states for all 280 simulated cells. Color is known simulated program; the outlined point is cell 1.-1.2-1.9-0.6-1.2-0.1-0.50.50.11.10.8Cell 1 · program 0.538 · trainCell 2 · program 0.060 · trainCell 3 · program -0.550 · trainCell 4 · program 1.754 · validationCell 5 · program 1.007 · trainCell 6 · program 0.097 · trainCell 7 · program 0.353 · testCell 8 · program 0.909 · trainCell 9 · program 0.006 · validationCell 10 · program 1.289 · trainCell 11 · program 0.486 · testCell 12 · program 0.802 · trainCell 13 · program -0.030 · trainCell 14 · program -1.764 · trainCell 15 · program 0.336 · trainCell 16 · program -0.637 · validationCell 17 · program 0.320 · trainCell 18 · program 0.474 · testCell 19 · program 0.531 · testCell 20 · program 1.363 · trainCell 21 · program -0.107 · trainCell 22 · program -2.277 · testCell 23 · program -0.537 · trainCell 24 · program -0.193 · trainCell 25 · program 0.405 · trainCell 26 · program 1.310 · validationCell 27 · program 1.192 · trainCell 28 · program 0.282 · trainCell 29 · program -0.279 · testCell 30 · program -0.220 · validationCell 31 · program 1.172 · testCell 32 · program -0.493 · trainCell 33 · program -1.563 · validationCell 34 · program 1.395 · trainCell 35 · program -0.347 · trainCell 36 · program 0.331 · validationCell 37 · program -0.659 · trainCell 38 · program 0.051 · trainCell 39 · program 1.089 · trainCell 40 · program -0.889 · trainCell 41 · program 0.158 · trainCell 42 · program 0.556 · trainCell 43 · program 0.067 · trainCell 44 · program -1.215 · validationCell 45 · program -0.247 · trainCell 46 · program 0.448 · trainCell 47 · program -0.529 · trainCell 48 · program 0.048 · validationCell 49 · program 0.548 · trainCell 50 · program -1.220 · trainCell 51 · program -0.050 · validationCell 52 · program -0.798 · trainCell 53 · program 0.428 · trainCell 54 · program -1.655 · validationCell 55 · program 0.659 · trainCell 56 · program -0.962 · trainCell 57 · program -0.043 · trainCell 58 · program -0.855 · testCell 59 · program -0.477 · testCell 60 · program -0.698 · testCell 61 · program -0.435 · trainCell 62 · program 1.682 · validationCell 63 · program -0.624 · testCell 64 · program 0.005 · trainCell 65 · program -1.348 · testCell 66 · program -0.733 · testCell 67 · program -0.491 · trainCell 68 · program -0.489 · trainCell 69 · program -1.524 · trainCell 70 · program -0.449 · testCell 71 · program -0.580 · trainCell 72 · program -1.466 · validationCell 73 · program 0.756 · trainCell 74 · program 1.299 · trainCell 75 · program -1.062 · trainCell 76 · program -0.011 · validationCell 77 · program 1.098 · trainCell 78 · program -0.189 · testCell 79 · program -1.180 · trainCell 80 · program 1.804 · trainCell 81 · program -0.024 · trainCell 82 · program -1.364 · trainCell 83 · program -1.376 · testCell 84 · program -2.710 · testCell 85 · program -1.254 · trainCell 86 · program 0.839 · trainCell 87 · program 0.473 · trainCell 88 · program 0.842 · trainCell 89 · program -0.850 · testCell 90 · program 0.315 · trainCell 91 · program -1.740 · trainCell 92 · program -0.200 · trainCell 93 · program 0.534 · trainCell 94 · program 0.084 · validationCell 95 · program -0.110 · trainCell 96 · program -0.359 · trainCell 97 · program 0.199 · validationCell 98 · program -0.823 · testCell 99 · program 0.061 · trainCell 100 · program -1.444 · validationCell 101 · program -0.679 · trainCell 102 · program 0.210 · trainCell 103 · program 0.641 · validationCell 104 · program -0.797 · trainCell 105 · program -1.367 · trainCell 106 · program -0.719 · trainCell 107 · program 1.494 · trainCell 108 · program -1.755 · testCell 109 · program 0.219 · trainCell 110 · program -1.162 · trainCell 111 · program 0.957 · testCell 112 · program -2.306 · trainCell 113 · program -0.058 · trainCell 114 · program -2.301 · trainCell 115 · program 0.720 · trainCell 116 · program 0.353 · validationCell 117 · program -0.951 · trainCell 118 · program -0.267 · trainCell 119 · program -0.486 · trainCell 120 · program -1.237 · validationCell 121 · program 0.529 · validationCell 122 · program -0.639 · testCell 123 · program 1.167 · testCell 124 · program 0.391 · testCell 125 · program -1.711 · trainCell 126 · program 0.561 · trainCell 127 · program 1.277 · trainCell 128 · program 0.433 · validationCell 129 · program 1.275 · testCell 130 · program -0.421 · testCell 131 · program -0.167 · trainCell 132 · program -0.701 · trainCell 133 · program 1.663 · testCell 134 · program 0.537 · trainCell 135 · program -0.573 · trainCell 136 · program 0.323 · testCell 137 · program -0.167 · trainCell 138 · program 1.107 · validationCell 139 · program -0.850 · testCell 140 · program 1.421 · testCell 141 · program -0.514 · trainCell 142 · program 0.640 · trainCell 143 · program 0.050 · trainCell 144 · program -0.291 · trainCell 145 · program -0.807 · trainCell 146 · program -0.970 · trainCell 147 · program -0.690 · trainCell 148 · program 0.793 · trainCell 149 · program -0.659 · trainCell 150 · program -0.112 · trainCell 151 · program -1.167 · trainCell 152 · program 1.260 · trainCell 153 · program -1.730 · testCell 154 · program 0.252 · testCell 155 · program 1.747 · trainCell 156 · program 0.849 · validationCell 157 · program 1.334 · trainCell 158 · program -0.193 · trainCell 159 · program 0.661 · validationCell 160 · program -1.033 · trainCell 161 · program -1.628 · trainCell 162 · program 0.556 · testCell 163 · program -1.352 · trainCell 164 · program -1.069 · validationCell 165 · program 0.776 · trainCell 166 · program 2.992 · validationCell 167 · program 0.885 · testCell 168 · program 1.006 · trainCell 169 · program 0.467 · trainCell 170 · program -1.688 · trainCell 171 · program 0.228 · trainCell 172 · program 0.442 · testCell 173 · program -0.647 · trainCell 174 · program -1.054 · trainCell 175 · program 0.442 · trainCell 176 · program -0.497 · trainCell 177 · program -1.258 · trainCell 178 · program 0.162 · trainCell 179 · program 0.918 · validationCell 180 · program 0.340 · trainCell 181 · program 0.850 · trainCell 182 · program -0.994 · trainCell 183 · program -1.406 · trainCell 184 · program -0.696 · validationCell 185 · program 0.065 · testCell 186 · program -1.148 · trainCell 187 · program -1.815 · validationCell 188 · program 1.235 · trainCell 189 · program -0.182 · trainCell 190 · program -0.312 · validationCell 191 · program -1.221 · trainCell 192 · program -0.960 · trainCell 193 · program -0.925 · testCell 194 · program 0.762 · testCell 195 · program -0.501 · trainCell 196 · program -0.397 · trainCell 197 · program 1.154 · trainCell 198 · program -0.676 · trainCell 199 · program 1.407 · trainCell 200 · program 0.344 · trainCell 201 · program 1.253 · testCell 202 · program -0.579 · testCell 203 · program 0.596 · trainCell 204 · program -1.023 · trainCell 205 · program 0.071 · trainCell 206 · program -1.331 · trainCell 207 · program -0.163 · testCell 208 · program -0.579 · trainCell 209 · program -1.272 · trainCell 210 · program -0.356 · testCell 211 · program -1.305 · testCell 212 · program -0.744 · trainCell 213 · program -0.581 · trainCell 214 · program 0.279 · testCell 215 · program -0.720 · trainCell 216 · program 0.143 · trainCell 217 · program 0.129 · trainCell 218 · program -1.950 · testCell 219 · program -0.610 · trainCell 220 · program -0.390 · validationCell 221 · program -0.465 · testCell 222 · program -0.192 · trainCell 223 · program -0.392 · trainCell 224 · program -0.119 · trainCell 225 · program -0.163 · trainCell 226 · program -0.260 · trainCell 227 · program -0.640 · testCell 228 · program 0.813 · trainCell 229 · program -1.644 · validationCell 230 · program -1.062 · validationCell 231 · program -1.349 · trainCell 232 · program 1.424 · trainCell 233 · program -1.617 · testCell 234 · program 0.216 · trainCell 235 · program 0.306 · trainCell 236 · program 0.570 · validationCell 237 · program -0.697 · testCell 238 · program -1.026 · trainCell 239 · program 0.688 · trainCell 240 · program 1.806 · trainCell 241 · program -1.437 · trainCell 242 · program 1.088 · trainCell 243 · program 1.169 · testCell 244 · program -0.955 · validationCell 245 · program -1.801 · testCell 246 · program 0.192 · trainCell 247 · program -0.248 · trainCell 248 · program -0.819 · trainCell 249 · program 0.022 · testCell 250 · program 1.856 · validationCell 251 · program -1.401 · trainCell 252 · program -0.165 · trainCell 253 · program -0.933 · trainCell 254 · program 2.875 · validationCell 255 · program 0.408 · testCell 256 · program -1.481 · validationCell 257 · program 1.693 · trainCell 258 · program -2.740 · testCell 259 · program 0.697 · trainCell 260 · program -0.977 · trainCell 261 · program -1.412 · validationCell 262 · program 0.452 · trainCell 263 · program 0.658 · trainCell 264 · program -0.385 · trainCell 265 · program 0.526 · trainCell 266 · program 1.265 · trainCell 267 · program -1.787 · validationCell 268 · program -0.932 · trainCell 269 · program 0.107 · trainCell 270 · program -0.193 · trainCell 271 · program -2.040 · trainCell 272 · program 0.926 · trainCell 273 · program 0.314 · trainCell 274 · program 0.942 · trainCell 275 · program 0.011 · testCell 276 · program -0.429 · trainCell 277 · program -0.660 · validationCell 278 · program 1.482 · testCell 279 · program -0.077 · trainCell 280 · program 0.140 · trainDecipher v₁Decipher v₂-2.73.0Known simulated program

RNA + ATAC · cell 1 · v = [0.966, -0.867] · known program 0.840 · training cell. Positions come from this model run; no trajectory is fitted here.

dExpression and accessibility across the program
Observed profiles of gene_0 and peak_0 across ten equal-count bins of the known simulated program. Each bin contains 28 cells. The selected cell is in bin 8.gene_0 · observed RNA0.00-2.71.54-1.33.080.14.621.66.163.0Bin 1 · n = 28 · Mean log-normalized count: 5.4981Bin 2 · n = 28 · Mean log-normalized count: 5.3504Bin 3 · n = 28 · Mean log-normalized count: 5.4062Bin 4 · n = 28 · Mean log-normalized count: 5.1377Bin 5 · n = 28 · Mean log-normalized count: 4.5346Bin 6 · n = 28 · Mean log-normalized count: 4.5982Bin 7 · n = 28 · Mean log-normalized count: 4.7589Bin 8 · n = 28 · Mean log-normalized count: 4.0152Bin 9 · n = 28 · Mean log-normalized count: 4.2550Bin 10 · n = 28 · Mean log-normalized count: 3.6899Known simulated programMean log-normalized countpeak_0 · observed accessibility0.00-2.70.25-1.30.500.10.751.61.003.0Bin 1 · n = 28 · Fraction of cells accessible: 0.7857Bin 2 · n = 28 · Fraction of cells accessible: 0.6071Bin 3 · n = 28 · Fraction of cells accessible: 0.3929Bin 4 · n = 28 · Fraction of cells accessible: 0.4643Bin 5 · n = 28 · Fraction of cells accessible: 0.5357Bin 6 · n = 28 · Fraction of cells accessible: 0.2857Bin 7 · n = 28 · Fraction of cells accessible: 0.1786Bin 8 · n = 28 · Fraction of cells accessible: 0.1071Bin 9 · n = 28 · Fraction of cells accessible: 0.0714Bin 10 · n = 28 · Fraction of cells accessible: 0.0714Known simulated programFraction of cells accessiblePoints: bin means · dashed line: selected cell’s bin · both models use these same inputs

Cell 1 is in program bin 9/10 (28 cells). This cell: gene_0 = 35 raw counts; peak_0 = closed. Bin means: RNA 5.124; ATAC accessibility 50.0%. Profiles summarize the same observed inputs for both model configurations.

Observed inputs grouped by the known simulation variable: 10 bins × 28 cells. These are not decoder-generated trajectories or an inferred peak-to-gene link. Feature names are simulation labels.

eDid ATAC improve recovery of the hidden program?Same 56 untouched test cells
Program recovery on 56 untouched test cells: RNA-only R squared 0.430; RNA plus ATAC 0.601.Test program recovery · R²0.000.250.500.751.00RNA-only ablation0.430RNA + ATAC0.601Normalization + dropout0.800Higher = more simulated-program variation recovered

Adding ATAC raises test R² from 0.430 to 0.601 in this run. Cell 1: known program 0.538, Normalization + dropout linear readout 0.697. This cell is used for training or validation and does not contribute to the test score.

The RNA-only model is an ablation of my extension. This benchmark contains 280 simulated paired cells, with deliberately stronger program information in ATAC. It does not establish improvement in patient samples.

Inspect all comparisons and learning curves ↓

How this changes the published Figure 1

The input panel now includes paired RNA and ATAC. The generative model adds a Bernoulli peak decoder alongside the RNA negative-binomial decoder. Shared-state coordinates come from my re-executed extension, and the last panel evaluates its held-out recovery.

The original HOXA9 example and basis decomposition belong to the published RNA workflow. My current fork has not yet exported multimodal trajectory decoding or learned RNA/ATAC basis decompositions, so those results are only shown in the published-reference view. The profiles here summarize observed simulated inputs using their known program values.

The profile calculation first normalizes each cell’s selected RNA count as log(1 + 10,000 × count / library size), then averages within each equal-count program bin. ATAC is the fraction of cells with accessibility 1. Both feature views use the same cells in each bin. Each graph has its own units and no regulatory association is assumed.

My local RNA + ATAC fork · September 21, 2026 run · 56 genes, 120 peaks, 6 shared factors and a 2D state. All displayed cells, counts, accessibility calls and recovery scores come from the exported run. Run provenance ↗ Validation selects each checkpoint; the test partition is separate. Repeated ablations are shown below.

Published Figure 1 reference
1 / 5 · Start with measured single-cell RNA

Reference and perturbed samples enter as cell-by-gene count matrices. These tiles show eight measured genes for twelve example cells from each tutorial condition; HOXA9 is outlined because it is the gene followed in the published example.

aInputs and biological questionMeasured input · conceptual overview
Reference and cancer count matrices flow through the Decipher model to diverging cell-state paths. Matrices use actual tutorial counts; branch diagram is conceptual.Reference · HealthyPerturbed · AML1Observed RNA counts8 genes · 12 cells / conditionDeciphervzxShared and diverging statesImmatureMatureDerailedConceptual phenotype diagram

Input 1/24 · Healthy · immature · source row 12001 · HOXA9: 0 raw counts.

Tile color shows per-gene log-normalized RNA expression; HOXA9 is outlined. The readout gives the original count.

bDeep generative model
Decipher probabilistic graphical model: v generates z, then x with library size and dispersion. The alternate view highlights amortized inference.Cell iGene gv2D statez10 factorsxℓθGeneration: v → z → xv ~ N(0, I₂)z | v ~ N(gμ(v), diag(gσ(v)²))xᵢg ~ NB(ℓᵢ · f(zᵢ)g, θg)

Selected input: HOXA9 x = 0, library size ℓ = 8,212; stored v = (2.05, -0.76). Diagram only: no decoder is run here.

Method diagram + stored tutorial values

cPaths and cell states
ReferenceDisease
Vector redraw of the published Figure 1c example, with traced reference and disease paths. Graphical marks are not individual cell records.Decipher component 1Decipher component 2Start ● → cluster checkpoints → endpoint

Markers follow the paths drawn in Figure 1c. The colored marks reproduce the printed cloud; they are not individual cell records.

Traced from the published figure

Inspect the actual cell annotations
Actual saved tutorial coordinates colored by source cell annotations. These points are independent of the traced figure geometry above.Saved cell-state annotationsStored Decipher component 1
blast0blast1blast2blast3eryimmaturelymphomep

Actual saved tutorial coordinates: 2,000 displayed cells, colored by source annotation. The ring marks the selected input cell. This is a separate view from the traced example above.

dGene-expression patterns

v(t) → z(t) → expected xg(t)

HOXA9 mean expression lines traced from Figure 1d. Approximate graphical values; uncertainty bands are not reconstructed.HOXA9 · published example01234Relative position in published panelApproximate figure expression scale

Figure position 35% · reference ≈0.72 · disease ≈2.65. Mean lines traced from the figure; uncertainty bands omitted.

With trained decoder weights, Decipher evaluates gene expression along the path—even between observed cells.

Mean curves traced from Figure 1d

dHow shared patterns combineFigure reconstruction · coefficients refit

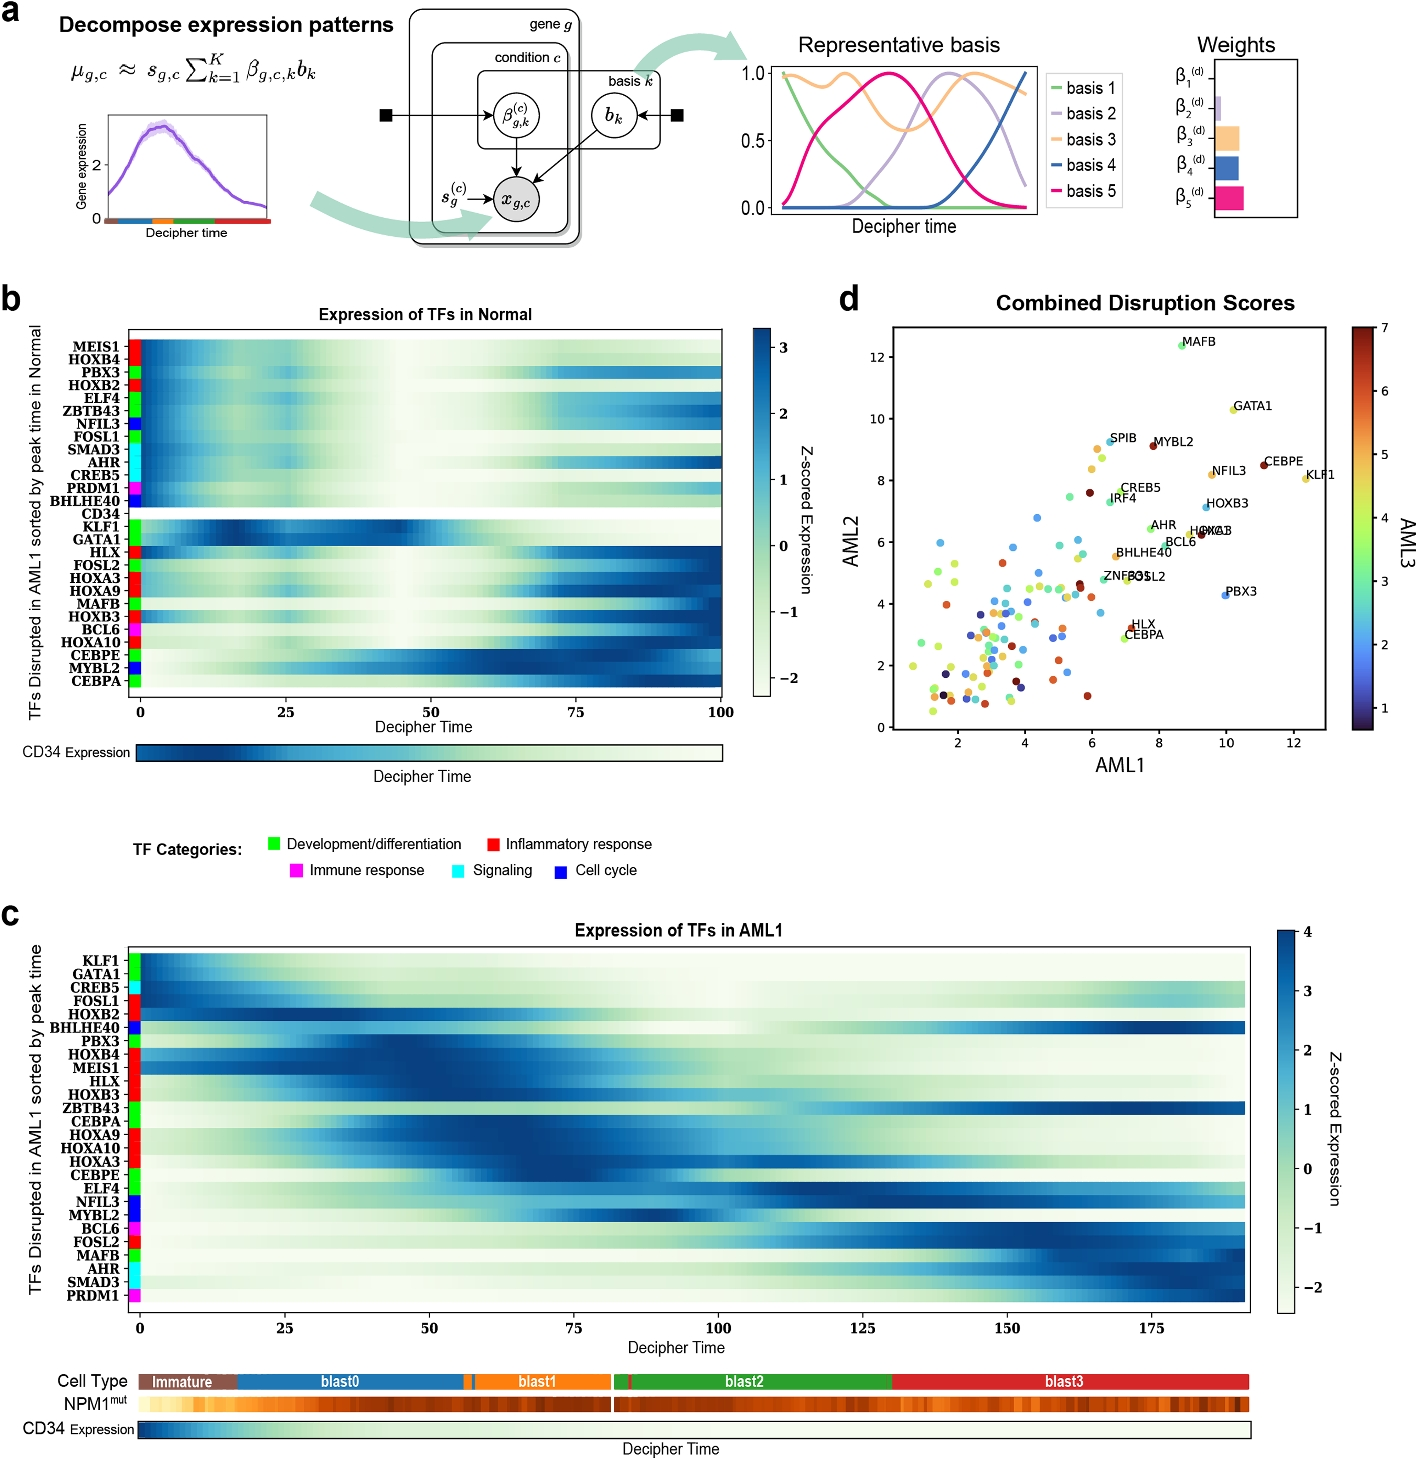
The same basis shapes can describe both conditions with different weights and expression scales. Toggle a component to see what it contributes to the reconstructed HOXA9 curve.

Five basis shapes traced from the published figure, shared between conditions.Shared basis shapes0.000.250.500.751.00Relative position in published panel
Weights refit to the digitized figure curves solely for this visual reconstruction. These are not published model coefficients.Disease · refit weights0.00β00.11β10.30β20.27β30.32β4Scale s ≈ 5.95 · Σβ = 1
Approximate reconstruction of the published curve from traced basis functions and refit coefficients.Weighted sum01234Relative position in published panel

Expressiong,c(t) ≈ sg,c ∑k βg,c,k bk(t)

Disease reconstruction: 5/5 components included. Solid = selected weighted sum; dashed = traced publication curve. Full-fit RMSE ≈0.095 figure units. Weights were refit to the traced artwork, not recovered from the trained Decipher model.

What is measured, traced, and reconstructed?

Measured / saved: the input matrices and selected-cell values come from the lab’s public tutorial dataset. The original cell inspectors below continue to use saved fitted coordinates.

Traced: the trajectory geometry, HOXA9 mean lines, and five basis shapes are digitized from the original Figure 1 artwork. They reproduce a published example, with graphical approximation. The scrubber uses relative position, not the paper’s shared arc-length Decipher time.

Reconstructed: nonnegative coefficients were refit to the traced curves to demonstrate the basis sum. They are not the paper’s posterior coefficients. No decoder, new biological trajectory, or clinical prediction is trained in this walkthrough.

In the actual method, shared basis functions are learned as neural networks, normalized to unit maximum; condition-specific β weights and scale s describe each gene pattern. The public tutorial file used here does not include the trained decoder checkpoint or trajectory/basis outputs.

Adapted from Nazaret, Fan, Lavallée et al. (2025), Figure 1 ↗ · CC BY 4.0 · Basis-decomposition implementation ↗. Continue to the data explorers below ↓

DECIPHER / TRAJECTORY EVALUATION
Does adding ATAC preserve the biology?
Held-out evaluation

Predicting a signal is only part of the test. Here I compare cell ordering, branching geometry, and expression trends—the structure Decipher was designed to make interpretable.

Results depend on what is being measured. In the earlier-ATAC simulation, mean 2D geometry scores were 0.849 for RNA + ATAC, 0.789 for the RNA-only ablation, and 0.671 for the upstream architecture. Normalization + dropout scored 0.821. With uninformative ATAC, joint geometry fell to 0.836, below RNA-only at 0.879.

On the public A549 time course, ordering correlations were 0.031 for RNA + ATAC, 0.526 for the RNA-only ablation, and 0.425 for upstream Decipher. These tests do not establish a general improvement over Decipher or validated cancer-lineage recovery.

Swipe plots sideways to see every axis.

Reference and perturbed branches

Simulated paired RNA and ATAC measurements with a known shared starting state and a divergence at progression 0.40. Five scenarios test when accessibility helps, repeats RNA, carries no biological signal, or includes technical variation.

Known trajectory simulation ground truth
Known simulated states-0.08-0.690.30-0.230.690.231.080.69True progressionTrue branch displacementTest cell 1; condition: 0.000Test cell 2; condition: 1.000Test cell 3; condition: 1.000Test cell 4; condition: 0.000Test cell 5; condition: 1.000Test cell 6; condition: 1.000Test cell 7; condition: 1.000Test cell 8; condition: 0.000Test cell 9; condition: 0.000Test cell 10; condition: 0.000Test cell 11; condition: 0.000Test cell 12; condition: 0.000Test cell 13; condition: 0.000Test cell 14; condition: 1.000Test cell 15; condition: 1.000Test cell 16; condition: 1.000Test cell 17; condition: 1.000Test cell 18; condition: 1.000Test cell 19; condition: 0.000Test cell 20; condition: 1.000Test cell 21; condition: 1.000Test cell 22; condition: 1.000Test cell 23; condition: 0.000Test cell 24; condition: 1.000Test cell 25; condition: 1.000Test cell 26; condition: 0.000Test cell 27; condition: 1.000Test cell 28; condition: 0.000Test cell 29; condition: 1.000Test cell 30; condition: 1.000Test cell 31; condition: 0.000Test cell 32; condition: 0.000Test cell 33; condition: 0.000Test cell 34; condition: 0.000Test cell 35; condition: 1.000Test cell 36; condition: 0.000Test cell 37; condition: 1.000Test cell 38; condition: 0.000Test cell 39; condition: 1.000Test cell 40; condition: 1.000Test cell 41; condition: 1.000Test cell 42; condition: 0.000Test cell 43; condition: 1.000Test cell 44; condition: 1.000Test cell 45; condition: 0.000Test cell 46; condition: 0.000Test cell 47; condition: 1.000Test cell 48; condition: 0.000Test cell 49; condition: 0.000Test cell 50; condition: 1.000Test cell 51; condition: 0.000Test cell 52; condition: 0.000Test cell 53; condition: 0.000Test cell 54; condition: 1.000Test cell 55; condition: 1.000Test cell 56; condition: 1.000Test cell 57; condition: 1.000Test cell 58; condition: 1.000Test cell 59; condition: 0.000Test cell 60; condition: 0.000Test cell 61; condition: 1.000Test cell 62; condition: 0.000Test cell 63; condition: 1.000Test cell 64; condition: 1.000Test cell 65; condition: 1.000Test cell 66; condition: 1.000Test cell 67; condition: 0.000Test cell 68; condition: 1.000Test cell 69; condition: 0.000Test cell 70; condition: 0.000Test cell 71; condition: 0.000Test cell 72; condition: 1.000Test cell 73; condition: 1.000Test cell 74; condition: 0.000Test cell 75; condition: 0.000Test cell 76; condition: 0.000Test cell 77; condition: 0.000Test cell 78; condition: 1.000Test cell 79; condition: 0.000Test cell 80; condition: 1.000Test cell 81; condition: 0.000Test cell 82; condition: 1.000Test cell 83; condition: 0.000Test cell 84; condition: 0.000Test cell 85; condition: 1.000Test cell 86; condition: 1.000Test cell 87; condition: 1.000Test cell 88; condition: 0.000Test cell 89; condition: 0.000Test cell 90; condition: 1.000Test cell 91; condition: 0.000Test cell 92; condition: 1.000Test cell 93; condition: 1.000Test cell 94; condition: 0.000Test cell 95; condition: 0.000Test cell 96; condition: 1.000Test cell 97; condition: 0.000Test cell 98; condition: 0.000Test cell 99; condition: 0.000Test cell 100; condition: 0.000Test cell 101; condition: 1.000Test cell 102; condition: 0.000Test cell 103; condition: 0.000Test cell 104; condition: 0.000Test cell 105; condition: 1.000Test cell 106; condition: 1.000Test cell 107; condition: 0.000Test cell 108; condition: 0.000Test cell 109; condition: 0.000Test cell 110; condition: 1.000Test cell 111; condition: 0.000Test cell 112; condition: 0.000Test cell 113; condition: 0.000Test cell 114; condition: 0.000Test cell 115; condition: 1.000Test cell 116; condition: 1.000Test cell 117; condition: 1.000Test cell 118; condition: 1.000Test cell 119; condition: 0.000Test cell 120; condition: 1.000
RNA + ATAC · 2D
Held-out cell coordinates-2.17-1.96-0.25-0.171.681.623.613.41Component 1Component 2Test cell 1; condition: 0.000Test cell 2; condition: 1.000Test cell 3; condition: 1.000Test cell 4; condition: 0.000Test cell 5; condition: 1.000Test cell 6; condition: 1.000Test cell 7; condition: 1.000Test cell 8; condition: 0.000Test cell 9; condition: 0.000Test cell 10; condition: 0.000Test cell 11; condition: 0.000Test cell 12; condition: 0.000Test cell 13; condition: 0.000Test cell 14; condition: 1.000Test cell 15; condition: 1.000Test cell 16; condition: 1.000Test cell 17; condition: 1.000Test cell 18; condition: 1.000Test cell 19; condition: 0.000Test cell 20; condition: 1.000Test cell 21; condition: 1.000Test cell 22; condition: 1.000Test cell 23; condition: 0.000Test cell 24; condition: 1.000Test cell 25; condition: 1.000Test cell 26; condition: 0.000Test cell 27; condition: 1.000Test cell 28; condition: 0.000Test cell 29; condition: 1.000Test cell 30; condition: 1.000Test cell 31; condition: 0.000Test cell 32; condition: 0.000Test cell 33; condition: 0.000Test cell 34; condition: 0.000Test cell 35; condition: 1.000Test cell 36; condition: 0.000Test cell 37; condition: 1.000Test cell 38; condition: 0.000Test cell 39; condition: 1.000Test cell 40; condition: 1.000Test cell 41; condition: 1.000Test cell 42; condition: 0.000Test cell 43; condition: 1.000Test cell 44; condition: 1.000Test cell 45; condition: 0.000Test cell 46; condition: 0.000Test cell 47; condition: 1.000Test cell 48; condition: 0.000Test cell 49; condition: 0.000Test cell 50; condition: 1.000Test cell 51; condition: 0.000Test cell 52; condition: 0.000Test cell 53; condition: 0.000Test cell 54; condition: 1.000Test cell 55; condition: 1.000Test cell 56; condition: 1.000Test cell 57; condition: 1.000Test cell 58; condition: 1.000Test cell 59; condition: 0.000Test cell 60; condition: 0.000Test cell 61; condition: 1.000Test cell 62; condition: 0.000Test cell 63; condition: 1.000Test cell 64; condition: 1.000Test cell 65; condition: 1.000Test cell 66; condition: 1.000Test cell 67; condition: 0.000Test cell 68; condition: 1.000Test cell 69; condition: 0.000Test cell 70; condition: 0.000Test cell 71; condition: 0.000Test cell 72; condition: 1.000Test cell 73; condition: 1.000Test cell 74; condition: 0.000Test cell 75; condition: 0.000Test cell 76; condition: 0.000Test cell 77; condition: 0.000Test cell 78; condition: 1.000Test cell 79; condition: 0.000Test cell 80; condition: 1.000Test cell 81; condition: 0.000Test cell 82; condition: 1.000Test cell 83; condition: 0.000Test cell 84; condition: 0.000Test cell 85; condition: 1.000Test cell 86; condition: 1.000Test cell 87; condition: 1.000Test cell 88; condition: 0.000Test cell 89; condition: 0.000Test cell 90; condition: 1.000Test cell 91; condition: 0.000Test cell 92; condition: 1.000Test cell 93; condition: 1.000Test cell 94; condition: 0.000Test cell 95; condition: 0.000Test cell 96; condition: 1.000Test cell 97; condition: 0.000Test cell 98; condition: 0.000Test cell 99; condition: 0.000Test cell 100; condition: 0.000Test cell 101; condition: 1.000Test cell 102; condition: 0.000Test cell 103; condition: 0.000Test cell 104; condition: 0.000Test cell 105; condition: 1.000Test cell 106; condition: 1.000Test cell 107; condition: 0.000Test cell 108; condition: 0.000Test cell 109; condition: 0.000Test cell 110; condition: 1.000Test cell 111; condition: 0.000Test cell 112; condition: 0.000Test cell 113; condition: 0.000Test cell 114; condition: 0.000Test cell 115; condition: 1.000Test cell 116; condition: 1.000Test cell 117; condition: 1.000Test cell 118; condition: 1.000Test cell 119; condition: 0.000Test cell 120; condition: 1.000

Teal: reference · Violet: perturbed. Lines show a training-fitted centroid tree; circles are held-out cells. Axes use each representation’s own scale.

Test cell 1 / 120 · Reference · true progression 0.381 · graph distance 2.133. Select a point or use the cell number control.

Global geometry (Kendall τ) · three independent runs
Global geometry (Kendall τ)-0.080.290.661.03Upstream DecipherUpstream Decipher: 0.671, 95% interval 0.587 to 0.755RNA-only ablationRNA-only ablation: 0.789, 95% interval 0.744 to 0.833RNA + ATACRNA + ATAC: 0.849, 95% interval 0.792 to 0.907Normalization + dropoutNormalization + dropout: 0.821, 95% interval 0.758 to 0.885MultiVIMultiVI: 0.832, 95% interval 0.723 to 0.941RNA PCARNA PCA: 0.691, 95% interval 0.675 to 0.706ATAC LSIATAC LSI: 0.712, 95% interval 0.675 to 0.749
Expression along progression synthetic branch marker · gene 1
Noise-free and neighborhood-recovered synthetic gene 1 trends-0.03-0.820.322.770.686.351.039.94True progressionGene 1 · log-panel10k

Solid: noise-free expected expression. Dashed: native v → z → RNA decoder estimate. Test cells are grouped by their true time for this diagnostic; time does not enter the model.

Higher is better. Selected run: RNA + ATAC, 0.823. Small dots are individual runs; large dots and whiskers show means and 95% t intervals. Intervals are based on only three runs.

How these scores are measured

The geometry score uses the lab’s mean intercluster-distance Kendall metric. The clusters come from known simulated states for scoring only. Ordering uses a 15-neighbor graph fitted on training cells, with spanning-tree edges to connect gaps. Only immature training cells identify the root; test times never orient or fit the graph.

Branch-point location uses a separate 20-centroid spanning tree. It is an exploratory diagnostic, not proof of lineage topology. A missing non-root junction receives error 1. Early condition mixing should be near 0.5; late branch separation is measured after progression 0.70.

The common gene-trend comparison uses the same 15-neighbor RNA smoother for every method. A separate native-decoder score evaluates the Decipher mapping from v through z to RNA. MultiVI and linear baselines do not receive that score. Every model uses a fixed 120-epoch budget with validation checkpoint selection; settings were frozen before these tests. Three runs provide limited precision. Some validation-selected checkpoints reached the 120-epoch limit; this comparison does not establish convergence or a fully tuned ranking.

Selected metric · mean and 95% t interval across three runs
ModelMean95% interval
Upstream Decipher0.6710.587 to 0.755
RNA-only ablation0.7890.744 to 0.833
RNA + ATAC0.8490.792 to 0.907
Normalization + dropout0.8210.758 to 0.885
MultiVI0.8320.723 to 0.941
RNA PCA0.6910.675 to 0.706
ATAC LSI0.7120.675 to 0.749
A check against independently recorded time

Public sci-CAR measurements pair RNA and chromatin accessibility in A549 cells collected 0, 1, or 3 hours after dexamethasone treatment. Collection time was recorded by the experiment; it was not generated by this model.

RNA + ATAC · 2D · 660 test cells
Held-out cell coordinates-2.03-1.51-1.12-0.50-0.210.510.691.52Component 1Component 2Test cell 1; collection time (hours): 1.000Test cell 2; collection time (hours): 0.000Test cell 3; collection time (hours): 1.000Test cell 4; collection time (hours): 1.000Test cell 5; collection time (hours): 1.000Test cell 6; collection time (hours): 0.000Test cell 7; collection time (hours): 3.000Test cell 8; collection time (hours): 0.000Test cell 9; collection time (hours): 0.000Test cell 10; collection time (hours): 3.000Test cell 11; collection time (hours): 0.000Test cell 12; collection time (hours): 1.000Test cell 13; collection time (hours): 1.000Test cell 14; collection time (hours): 1.000Test cell 15; collection time (hours): 3.000Test cell 16; collection time (hours): 1.000Test cell 17; collection time (hours): 3.000Test cell 18; collection time (hours): 1.000Test cell 19; collection time (hours): 1.000Test cell 20; collection time (hours): 0.000Test cell 21; collection time (hours): 3.000Test cell 22; collection time (hours): 0.000Test cell 23; collection time (hours): 3.000Test cell 24; collection time (hours): 3.000Test cell 25; collection time (hours): 0.000Test cell 26; collection time (hours): 3.000Test cell 27; collection time (hours): 1.000Test cell 28; collection time (hours): 0.000Test cell 29; collection time (hours): 3.000Test cell 30; collection time (hours): 1.000Test cell 31; collection time (hours): 1.000Test cell 32; collection time (hours): 0.000Test cell 33; collection time (hours): 1.000Test cell 34; collection time (hours): 1.000Test cell 35; collection time (hours): 3.000Test cell 36; collection time (hours): 1.000Test cell 37; collection time (hours): 1.000Test cell 38; collection time (hours): 1.000Test cell 39; collection time (hours): 3.000Test cell 40; collection time (hours): 3.000Test cell 41; collection time (hours): 1.000Test cell 42; collection time (hours): 3.000Test cell 43; collection time (hours): 1.000Test cell 44; collection time (hours): 0.000Test cell 45; collection time (hours): 3.000Test cell 46; collection time (hours): 3.000Test cell 47; collection time (hours): 0.000Test cell 48; collection time (hours): 3.000Test cell 49; collection time (hours): 3.000Test cell 50; collection time (hours): 0.000Test cell 51; collection time (hours): 3.000Test cell 52; collection time (hours): 1.000Test cell 53; collection time (hours): 0.000Test cell 54; collection time (hours): 0.000Test cell 55; collection time (hours): 0.000Test cell 56; collection time (hours): 3.000Test cell 57; collection time (hours): 3.000Test cell 58; collection time (hours): 3.000Test cell 59; collection time (hours): 3.000Test cell 60; collection time (hours): 1.000Test cell 61; collection time (hours): 3.000Test cell 62; collection time (hours): 1.000Test cell 63; collection time (hours): 0.000Test cell 64; collection time (hours): 0.000Test cell 65; collection time (hours): 1.000Test cell 66; collection time (hours): 3.000Test cell 67; collection time (hours): 3.000Test cell 68; collection time (hours): 0.000Test cell 69; collection time (hours): 3.000Test cell 70; collection time (hours): 1.000Test cell 71; collection time (hours): 1.000Test cell 72; collection time (hours): 0.000Test cell 73; collection time (hours): 0.000Test cell 74; collection time (hours): 1.000Test cell 75; collection time (hours): 1.000Test cell 76; collection time (hours): 3.000Test cell 77; collection time (hours): 1.000Test cell 78; collection time (hours): 0.000Test cell 79; collection time (hours): 0.000Test cell 80; collection time (hours): 0.000Test cell 81; collection time (hours): 3.000Test cell 82; collection time (hours): 0.000Test cell 83; collection time (hours): 1.000Test cell 84; collection time (hours): 0.000Test cell 85; collection time (hours): 0.000Test cell 86; collection time (hours): 1.000Test cell 87; collection time (hours): 0.000Test cell 88; collection time (hours): 0.000Test cell 89; collection time (hours): 3.000Test cell 90; collection time (hours): 3.000Test cell 91; collection time (hours): 1.000Test cell 92; collection time (hours): 1.000Test cell 93; collection time (hours): 3.000Test cell 94; collection time (hours): 1.000Test cell 95; collection time (hours): 0.000Test cell 96; collection time (hours): 0.000Test cell 97; collection time (hours): 1.000Test cell 98; collection time (hours): 1.000Test cell 99; collection time (hours): 0.000Test cell 100; collection time (hours): 3.000Test cell 101; collection time (hours): 1.000Test cell 102; collection time (hours): 1.000Test cell 103; collection time (hours): 3.000Test cell 104; collection time (hours): 1.000Test cell 105; collection time (hours): 1.000Test cell 106; collection time (hours): 1.000Test cell 107; collection time (hours): 3.000Test cell 108; collection time (hours): 3.000Test cell 109; collection time (hours): 3.000Test cell 110; collection time (hours): 0.000Test cell 111; collection time (hours): 1.000Test cell 112; collection time (hours): 1.000Test cell 113; collection time (hours): 3.000Test cell 114; collection time (hours): 0.000Test cell 115; collection time (hours): 1.000Test cell 116; collection time (hours): 1.000Test cell 117; collection time (hours): 3.000Test cell 118; collection time (hours): 3.000Test cell 119; collection time (hours): 3.000Test cell 120; collection time (hours): 1.000Test cell 121; collection time (hours): 0.000Test cell 122; collection time (hours): 1.000Test cell 123; collection time (hours): 0.000Test cell 124; collection time (hours): 1.000Test cell 125; collection time (hours): 3.000Test cell 126; collection time (hours): 1.000Test cell 127; collection time (hours): 1.000Test cell 128; collection time (hours): 3.000Test cell 129; collection time (hours): 1.000Test cell 130; collection time (hours): 3.000Test cell 131; collection time (hours): 0.000Test cell 132; collection time (hours): 1.000Test cell 133; collection time (hours): 1.000Test cell 134; collection time (hours): 3.000Test cell 135; collection time (hours): 3.000Test cell 136; collection time (hours): 3.000Test cell 137; collection time (hours): 1.000Test cell 138; collection time (hours): 0.000Test cell 139; collection time (hours): 3.000Test cell 140; collection time (hours): 1.000Test cell 141; collection time (hours): 0.000Test cell 142; collection time (hours): 3.000Test cell 143; collection time (hours): 0.000Test cell 144; collection time (hours): 1.000Test cell 145; collection time (hours): 1.000Test cell 146; collection time (hours): 3.000Test cell 147; collection time (hours): 0.000Test cell 148; collection time (hours): 1.000Test cell 149; collection time (hours): 3.000Test cell 150; collection time (hours): 3.000Test cell 151; collection time (hours): 1.000Test cell 152; collection time (hours): 3.000Test cell 153; collection time (hours): 1.000Test cell 154; collection time (hours): 3.000Test cell 155; collection time (hours): 0.000Test cell 156; collection time (hours): 1.000Test cell 157; collection time (hours): 1.000Test cell 158; collection time (hours): 1.000Test cell 159; collection time (hours): 1.000Test cell 160; collection time (hours): 3.000Test cell 161; collection time (hours): 3.000Test cell 162; collection time (hours): 0.000Test cell 163; collection time (hours): 3.000Test cell 164; collection time (hours): 3.000Test cell 165; collection time (hours): 3.000Test cell 166; collection time (hours): 0.000Test cell 167; collection time (hours): 0.000Test cell 168; collection time (hours): 3.000Test cell 169; collection time (hours): 3.000Test cell 170; collection time (hours): 1.000Test cell 171; collection time (hours): 1.000Test cell 172; collection time (hours): 0.000Test cell 173; collection time (hours): 3.000Test cell 174; collection time (hours): 1.000Test cell 175; collection time (hours): 3.000Test cell 176; collection time (hours): 3.000Test cell 177; collection time (hours): 0.000Test cell 178; collection time (hours): 3.000Test cell 179; collection time (hours): 0.000Test cell 180; collection time (hours): 3.000Test cell 181; collection time (hours): 0.000Test cell 182; collection time (hours): 0.000Test cell 183; collection time (hours): 3.000Test cell 184; collection time (hours): 1.000Test cell 185; collection time (hours): 3.000Test cell 186; collection time (hours): 3.000Test cell 187; collection time (hours): 0.000Test cell 188; collection time (hours): 1.000Test cell 189; collection time (hours): 0.000Test cell 190; collection time (hours): 3.000Test cell 191; collection time (hours): 3.000Test cell 192; collection time (hours): 3.000Test cell 193; collection time (hours): 3.000Test cell 194; collection time (hours): 1.000Test cell 195; collection time (hours): 3.000Test cell 196; collection time (hours): 3.000Test cell 197; collection time (hours): 3.000Test cell 198; collection time (hours): 0.000Test cell 199; collection time (hours): 3.000Test cell 200; collection time (hours): 1.000Test cell 201; collection time (hours): 1.000Test cell 202; collection time (hours): 3.000Test cell 203; collection time (hours): 1.000Test cell 204; collection time (hours): 3.000Test cell 205; collection time (hours): 3.000Test cell 206; collection time (hours): 1.000Test cell 207; collection time (hours): 3.000Test cell 208; collection time (hours): 1.000Test cell 209; collection time (hours): 3.000Test cell 210; collection time (hours): 1.000Test cell 211; collection time (hours): 3.000Test cell 212; collection time (hours): 1.000Test cell 213; collection time (hours): 3.000Test cell 214; collection time (hours): 3.000Test cell 215; collection time (hours): 0.000Test cell 216; collection time (hours): 1.000Test cell 217; collection time (hours): 3.000Test cell 218; collection time (hours): 1.000Test cell 219; collection time (hours): 0.000Test cell 220; collection time (hours): 1.000Test cell 221; collection time (hours): 1.000Test cell 222; collection time (hours): 0.000Test cell 223; collection time (hours): 3.000Test cell 224; collection time (hours): 3.000Test cell 225; collection time (hours): 1.000Test cell 226; collection time (hours): 0.000Test cell 227; collection time (hours): 0.000Test cell 228; collection time (hours): 1.000Test cell 229; collection time (hours): 1.000Test cell 230; collection time (hours): 0.000Test cell 231; collection time (hours): 0.000Test cell 232; collection time (hours): 1.000Test cell 233; collection time (hours): 1.000Test cell 234; collection time (hours): 3.000Test cell 235; collection time (hours): 3.000Test cell 236; collection time (hours): 1.000Test cell 237; collection time (hours): 3.000Test cell 238; collection time (hours): 0.000Test cell 239; collection time (hours): 0.000Test cell 240; collection time (hours): 3.000Test cell 241; collection time (hours): 3.000Test cell 242; collection time (hours): 1.000Test cell 243; collection time (hours): 1.000Test cell 244; collection time (hours): 1.000Test cell 245; collection time (hours): 3.000Test cell 246; collection time (hours): 0.000Test cell 247; collection time (hours): 0.000Test cell 248; collection time (hours): 3.000Test cell 249; collection time (hours): 0.000Test cell 250; collection time (hours): 0.000Test cell 251; collection time (hours): 3.000Test cell 252; collection time (hours): 3.000Test cell 253; collection time (hours): 1.000Test cell 254; collection time (hours): 1.000Test cell 255; collection time (hours): 1.000Test cell 256; collection time (hours): 0.000Test cell 257; collection time (hours): 3.000Test cell 258; collection time (hours): 3.000Test cell 259; collection time (hours): 0.000Test cell 260; collection time (hours): 3.000Test cell 261; collection time (hours): 0.000Test cell 262; collection time (hours): 3.000Test cell 263; collection time (hours): 1.000Test cell 264; collection time (hours): 3.000Test cell 265; collection time (hours): 1.000Test cell 266; collection time (hours): 1.000Test cell 267; collection time (hours): 1.000Test cell 268; collection time (hours): 0.000Test cell 269; collection time (hours): 3.000Test cell 270; collection time (hours): 0.000Test cell 271; collection time (hours): 3.000Test cell 272; collection time (hours): 3.000Test cell 273; collection time (hours): 1.000Test cell 274; collection time (hours): 3.000Test cell 275; collection time (hours): 1.000Test cell 276; collection time (hours): 1.000Test cell 277; collection time (hours): 3.000Test cell 278; collection time (hours): 1.000Test cell 279; collection time (hours): 1.000Test cell 280; collection time (hours): 3.000Test cell 281; collection time (hours): 1.000Test cell 282; collection time (hours): 1.000Test cell 283; collection time (hours): 0.000Test cell 284; collection time (hours): 3.000Test cell 285; collection time (hours): 0.000Test cell 286; collection time (hours): 1.000Test cell 287; collection time (hours): 3.000Test cell 288; collection time (hours): 1.000Test cell 289; collection time (hours): 1.000Test cell 290; collection time (hours): 1.000Test cell 291; collection time (hours): 3.000Test cell 292; collection time (hours): 3.000Test cell 293; collection time (hours): 3.000Test cell 294; collection time (hours): 3.000Test cell 295; collection time (hours): 3.000Test cell 296; collection time (hours): 3.000Test cell 297; collection time (hours): 1.000Test cell 298; collection time (hours): 1.000Test cell 299; collection time (hours): 1.000Test cell 300; collection time (hours): 1.000Test cell 301; collection time (hours): 1.000Test cell 302; collection time (hours): 3.000Test cell 303; collection time (hours): 1.000Test cell 304; collection time (hours): 0.000Test cell 305; collection time (hours): 3.000Test cell 306; collection time (hours): 1.000Test cell 307; collection time (hours): 3.000Test cell 308; collection time (hours): 1.000Test cell 309; collection time (hours): 3.000Test cell 310; collection time (hours): 1.000Test cell 311; collection time (hours): 0.000Test cell 312; collection time (hours): 1.000Test cell 313; collection time (hours): 3.000Test cell 314; collection time (hours): 1.000Test cell 315; collection time (hours): 0.000Test cell 316; collection time (hours): 3.000Test cell 317; collection time (hours): 3.000Test cell 318; collection time (hours): 3.000Test cell 319; collection time (hours): 1.000Test cell 320; collection time (hours): 1.000Test cell 321; collection time (hours): 0.000Test cell 322; collection time (hours): 1.000Test cell 323; collection time (hours): 0.000Test cell 324; collection time (hours): 0.000Test cell 325; collection time (hours): 3.000Test cell 326; collection time (hours): 1.000Test cell 327; collection time (hours): 1.000Test cell 328; collection time (hours): 0.000Test cell 329; collection time (hours): 1.000Test cell 330; collection time (hours): 0.000Test cell 331; collection time (hours): 3.000Test cell 332; collection time (hours): 3.000Test cell 333; collection time (hours): 1.000Test cell 334; collection time (hours): 3.000Test cell 335; collection time (hours): 3.000Test cell 336; collection time (hours): 3.000Test cell 337; collection time (hours): 1.000Test cell 338; collection time (hours): 3.000Test cell 339; collection time (hours): 1.000Test cell 340; collection time (hours): 3.000Test cell 341; collection time (hours): 0.000Test cell 342; collection time (hours): 3.000Test cell 343; collection time (hours): 1.000Test cell 344; collection time (hours): 3.000Test cell 345; collection time (hours): 1.000Test cell 346; collection time (hours): 1.000Test cell 347; collection time (hours): 3.000Test cell 348; collection time (hours): 3.000Test cell 349; collection time (hours): 1.000Test cell 350; collection time (hours): 1.000Test cell 351; collection time (hours): 0.000Test cell 352; collection time (hours): 3.000Test cell 353; collection time (hours): 1.000Test cell 354; collection time (hours): 3.000Test cell 355; collection time (hours): 3.000Test cell 356; collection time (hours): 0.000Test cell 357; collection time (hours): 1.000Test cell 358; collection time (hours): 1.000Test cell 359; collection time (hours): 0.000Test cell 360; collection time (hours): 1.000Test cell 361; collection time (hours): 1.000Test cell 362; collection time (hours): 1.000Test cell 363; collection time (hours): 1.000Test cell 364; collection time (hours): 1.000Test cell 365; collection time (hours): 1.000Test cell 366; collection time (hours): 1.000Test cell 367; collection time (hours): 1.000Test cell 368; collection time (hours): 0.000Test cell 369; collection time (hours): 0.000Test cell 370; collection time (hours): 3.000Test cell 371; collection time (hours): 1.000Test cell 372; collection time (hours): 0.000Test cell 373; collection time (hours): 0.000Test cell 374; collection time (hours): 0.000Test cell 375; collection time (hours): 3.000Test cell 376; collection time (hours): 1.000Test cell 377; collection time (hours): 1.000Test cell 378; collection time (hours): 0.000Test cell 379; collection time (hours): 0.000Test cell 380; collection time (hours): 1.000Test cell 381; collection time (hours): 1.000Test cell 382; collection time (hours): 1.000Test cell 383; collection time (hours): 1.000Test cell 384; collection time (hours): 0.000Test cell 385; collection time (hours): 1.000Test cell 386; collection time (hours): 0.000Test cell 387; collection time (hours): 3.000Test cell 388; collection time (hours): 3.000Test cell 389; collection time (hours): 1.000Test cell 390; collection time (hours): 3.000Test cell 391; collection time (hours): 3.000Test cell 392; collection time (hours): 3.000Test cell 393; collection time (hours): 3.000Test cell 394; collection time (hours): 3.000Test cell 395; collection time (hours): 1.000Test cell 396; collection time (hours): 3.000Test cell 397; collection time (hours): 3.000Test cell 398; collection time (hours): 3.000Test cell 399; collection time (hours): 3.000Test cell 400; collection time (hours): 1.000Test cell 401; collection time (hours): 0.000Test cell 402; collection time (hours): 0.000Test cell 403; collection time (hours): 1.000Test cell 404; collection time (hours): 3.000Test cell 405; collection time (hours): 0.000Test cell 406; collection time (hours): 1.000Test cell 407; collection time (hours): 1.000Test cell 408; collection time (hours): 0.000Test cell 409; collection time (hours): 3.000Test cell 410; collection time (hours): 1.000Test cell 411; collection time (hours): 1.000Test cell 412; collection time (hours): 1.000Test cell 413; collection time (hours): 1.000Test cell 414; collection time (hours): 1.000Test cell 415; collection time (hours): 1.000Test cell 416; collection time (hours): 3.000Test cell 417; collection time (hours): 3.000Test cell 418; collection time (hours): 1.000Test cell 419; collection time (hours): 3.000Test cell 420; collection time (hours): 0.000Test cell 421; collection time (hours): 1.000Test cell 422; collection time (hours): 1.000Test cell 423; collection time (hours): 3.000Test cell 424; collection time (hours): 0.000Test cell 425; collection time (hours): 1.000Test cell 426; collection time (hours): 1.000Test cell 427; collection time (hours): 3.000Test cell 428; collection time (hours): 3.000Test cell 429; collection time (hours): 1.000Test cell 430; collection time (hours): 1.000Test cell 431; collection time (hours): 1.000Test cell 432; collection time (hours): 3.000Test cell 433; collection time (hours): 1.000Test cell 434; collection time (hours): 3.000Test cell 435; collection time (hours): 1.000Test cell 436; collection time (hours): 1.000Test cell 437; collection time (hours): 1.000Test cell 438; collection time (hours): 3.000Test cell 439; collection time (hours): 1.000Test cell 440; collection time (hours): 0.000Test cell 441; collection time (hours): 1.000Test cell 442; collection time (hours): 3.000Test cell 443; collection time (hours): 3.000Test cell 444; collection time (hours): 3.000Test cell 445; collection time (hours): 1.000Test cell 446; collection time (hours): 1.000Test cell 447; collection time (hours): 0.000Test cell 448; collection time (hours): 0.000Test cell 449; collection time (hours): 3.000Test cell 450; collection time (hours): 1.000Test cell 451; collection time (hours): 0.000Test cell 452; collection time (hours): 3.000Test cell 453; collection time (hours): 1.000Test cell 454; collection time (hours): 1.000Test cell 455; collection time (hours): 1.000Test cell 456; collection time (hours): 1.000Test cell 457; collection time (hours): 1.000Test cell 458; collection time (hours): 3.000Test cell 459; collection time (hours): 3.000Test cell 460; collection time (hours): 3.000Test cell 461; collection time (hours): 1.000Test cell 462; collection time (hours): 0.000Test cell 463; collection time (hours): 1.000Test cell 464; collection time (hours): 1.000Test cell 465; collection time (hours): 3.000Test cell 466; collection time (hours): 3.000Test cell 467; collection time (hours): 0.000Test cell 468; collection time (hours): 3.000Test cell 469; collection time (hours): 0.000Test cell 470; collection time (hours): 1.000Test cell 471; collection time (hours): 0.000Test cell 472; collection time (hours): 1.000Test cell 473; collection time (hours): 1.000Test cell 474; collection time (hours): 1.000Test cell 475; collection time (hours): 1.000Test cell 476; collection time (hours): 3.000Test cell 477; collection time (hours): 3.000Test cell 478; collection time (hours): 1.000Test cell 479; collection time (hours): 0.000Test cell 480; collection time (hours): 1.000Test cell 481; collection time (hours): 1.000Test cell 482; collection time (hours): 3.000Test cell 483; collection time (hours): 0.000Test cell 484; collection time (hours): 0.000Test cell 485; collection time (hours): 1.000Test cell 486; collection time (hours): 1.000Test cell 487; collection time (hours): 3.000Test cell 488; collection time (hours): 0.000Test cell 489; collection time (hours): 1.000Test cell 490; collection time (hours): 3.000Test cell 491; collection time (hours): 3.000Test cell 492; collection time (hours): 1.000Test cell 493; collection time (hours): 1.000Test cell 494; collection time (hours): 1.000Test cell 495; collection time (hours): 1.000Test cell 496; collection time (hours): 0.000Test cell 497; collection time (hours): 1.000Test cell 498; collection time (hours): 0.000Test cell 499; collection time (hours): 1.000Test cell 500; collection time (hours): 1.000Test cell 501; collection time (hours): 3.000Test cell 502; collection time (hours): 1.000Test cell 503; collection time (hours): 1.000Test cell 504; collection time (hours): 3.000Test cell 505; collection time (hours): 0.000Test cell 506; collection time (hours): 1.000Test cell 507; collection time (hours): 3.000Test cell 508; collection time (hours): 1.000Test cell 509; collection time (hours): 3.000Test cell 510; collection time (hours): 1.000Test cell 511; collection time (hours): 1.000Test cell 512; collection time (hours): 1.000Test cell 513; collection time (hours): 1.000Test cell 514; collection time (hours): 1.000Test cell 515; collection time (hours): 1.000Test cell 516; collection time (hours): 3.000Test cell 517; collection time (hours): 3.000Test cell 518; collection time (hours): 0.000Test cell 519; collection time (hours): 3.000Test cell 520; collection time (hours): 3.000Test cell 521; collection time (hours): 0.000Test cell 522; collection time (hours): 3.000Test cell 523; collection time (hours): 0.000Test cell 524; collection time (hours): 0.000Test cell 525; collection time (hours): 3.000Test cell 526; collection time (hours): 0.000Test cell 527; collection time (hours): 1.000Test cell 528; collection time (hours): 3.000Test cell 529; collection time (hours): 1.000Test cell 530; collection time (hours): 1.000Test cell 531; collection time (hours): 1.000Test cell 532; collection time (hours): 3.000Test cell 533; collection time (hours): 3.000Test cell 534; collection time (hours): 0.000Test cell 535; collection time (hours): 3.000Test cell 536; collection time (hours): 1.000Test cell 537; collection time (hours): 1.000Test cell 538; collection time (hours): 1.000Test cell 539; collection time (hours): 0.000Test cell 540; collection time (hours): 3.000Test cell 541; collection time (hours): 1.000Test cell 542; collection time (hours): 0.000Test cell 543; collection time (hours): 1.000Test cell 544; collection time (hours): 3.000Test cell 545; collection time (hours): 3.000Test cell 546; collection time (hours): 3.000Test cell 547; collection time (hours): 1.000Test cell 548; collection time (hours): 1.000Test cell 549; collection time (hours): 0.000Test cell 550; collection time (hours): 3.000Test cell 551; collection time (hours): 1.000Test cell 552; collection time (hours): 3.000Test cell 553; collection time (hours): 1.000Test cell 554; collection time (hours): 3.000Test cell 555; collection time (hours): 1.000Test cell 556; collection time (hours): 3.000Test cell 557; collection time (hours): 3.000Test cell 558; collection time (hours): 3.000Test cell 559; collection time (hours): 3.000Test cell 560; collection time (hours): 0.000Test cell 561; collection time (hours): 1.000Test cell 562; collection time (hours): 3.000Test cell 563; collection time (hours): 0.000Test cell 564; collection time (hours): 0.000Test cell 565; collection time (hours): 3.000Test cell 566; collection time (hours): 0.000Test cell 567; collection time (hours): 1.000Test cell 568; collection time (hours): 3.000Test cell 569; collection time (hours): 1.000Test cell 570; collection time (hours): 3.000Test cell 571; collection time (hours): 1.000Test cell 572; collection time (hours): 3.000Test cell 573; collection time (hours): 3.000Test cell 574; collection time (hours): 3.000Test cell 575; collection time (hours): 1.000Test cell 576; collection time (hours): 3.000Test cell 577; collection time (hours): 0.000Test cell 578; collection time (hours): 1.000Test cell 579; collection time (hours): 3.000Test cell 580; collection time (hours): 3.000Test cell 581; collection time (hours): 3.000Test cell 582; collection time (hours): 3.000Test cell 583; collection time (hours): 1.000Test cell 584; collection time (hours): 0.000Test cell 585; collection time (hours): 3.000Test cell 586; collection time (hours): 1.000Test cell 587; collection time (hours): 3.000Test cell 588; collection time (hours): 1.000Test cell 589; collection time (hours): 3.000Test cell 590; collection time (hours): 3.000Test cell 591; collection time (hours): 1.000Test cell 592; collection time (hours): 3.000Test cell 593; collection time (hours): 1.000Test cell 594; collection time (hours): 0.000Test cell 595; collection time (hours): 1.000Test cell 596; collection time (hours): 3.000Test cell 597; collection time (hours): 1.000Test cell 598; collection time (hours): 3.000Test cell 599; collection time (hours): 0.000Test cell 600; collection time (hours): 3.000Test cell 601; collection time (hours): 3.000Test cell 602; collection time (hours): 3.000Test cell 603; collection time (hours): 0.000Test cell 604; collection time (hours): 3.000Test cell 605; collection time (hours): 1.000Test cell 606; collection time (hours): 3.000Test cell 607; collection time (hours): 3.000Test cell 608; collection time (hours): 1.000Test cell 609; collection time (hours): 0.000Test cell 610; collection time (hours): 0.000Test cell 611; collection time (hours): 1.000Test cell 612; collection time (hours): 1.000Test cell 613; collection time (hours): 3.000Test cell 614; collection time (hours): 1.000Test cell 615; collection time (hours): 3.000Test cell 616; collection time (hours): 1.000Test cell 617; collection time (hours): 1.000Test cell 618; collection time (hours): 3.000Test cell 619; collection time (hours): 3.000Test cell 620; collection time (hours): 3.000Test cell 621; collection time (hours): 0.000Test cell 622; collection time (hours): 3.000Test cell 623; collection time (hours): 1.000Test cell 624; collection time (hours): 3.000Test cell 625; collection time (hours): 3.000Test cell 626; collection time (hours): 3.000Test cell 627; collection time (hours): 3.000Test cell 628; collection time (hours): 3.000Test cell 629; collection time (hours): 3.000Test cell 630; collection time (hours): 3.000Test cell 631; collection time (hours): 0.000Test cell 632; collection time (hours): 0.000Test cell 633; collection time (hours): 0.000Test cell 634; collection time (hours): 3.000Test cell 635; collection time (hours): 0.000Test cell 636; collection time (hours): 3.000Test cell 637; collection time (hours): 0.000Test cell 638; collection time (hours): 3.000Test cell 639; collection time (hours): 0.000Test cell 640; collection time (hours): 3.000Test cell 641; collection time (hours): 1.000Test cell 642; collection time (hours): 3.000Test cell 643; collection time (hours): 1.000Test cell 644; collection time (hours): 1.000Test cell 645; collection time (hours): 3.000Test cell 646; collection time (hours): 3.000Test cell 647; collection time (hours): 0.000Test cell 648; collection time (hours): 3.000Test cell 649; collection time (hours): 1.000Test cell 650; collection time (hours): 3.000Test cell 651; collection time (hours): 1.000Test cell 652; collection time (hours): 3.000Test cell 653; collection time (hours): 3.000Test cell 654; collection time (hours): 1.000Test cell 655; collection time (hours): 1.000Test cell 656; collection time (hours): 3.000Test cell 657; collection time (hours): 1.000Test cell 658; collection time (hours): 0.000Test cell 659; collection time (hours): 3.000Test cell 660; collection time (hours): 1.000
Agreement with collection time signed Spearman correlation · higher is better
Agreement with recorded time-0.330.060.450.84Upstream DecipherUpstream Decipher: 0.425, 95% interval 0.216 to 0.633RNA-only ablationRNA-only ablation: 0.526, 95% interval 0.307 to 0.746RNA + ATACRNA + ATAC: 0.031, 95% interval -0.177 to 0.240Normalization + dropoutNormalization + dropout: -0.052, 95% interval -0.107 to 0.003MultiVIMultiVI: -0.064, 95% interval -0.242 to 0.114RNA PCARNA PCA: -0.105, 95% interval -0.105 to -0.105ATAC LSIATAC LSI: -0.062, 95% interval -0.079 to -0.046

Teal: 0 hours · Coral: 1 hour · Violet: 3 hours. Each circle is a held-out cell.

Selected run: time correlation 0.087. Test cell 1: collected at 1 hours; inferred graph distance 0.542.

3,256 paired A549 cells passed coverage filters; 2,103 training and 660 held-out test cells. Each fit uses 600 RNA genes and 1,200 ATAC peaks selected on training cells.

These are public treatment-response data, not my Azizi Lab samples. Three collection times do not supply exact cellular pseudotime or establish branching cancer-lineage recovery. Repeated initializations measure optimization variation within one experiment, not biological replication.

Coverage, technical effects, and evaluation scope

RNA and ATAC barcodes must match, with consistent A549 treatment labels. Basic coverage filters require at least 100 RNA counts and 20 accessible peaks. Features are selected only on training cells. Barcode-prefix groups remain together across training, validation, and test partitions. These are technical groups, not patients.

The 0-hour training cells identify the root. No 1-hour or 3-hour labels fit the trajectory, and no held-out labels select settings or reverse the trajectory. Depth correlations below help reveal technical structure; they do not remove it.

2D ordering and absolute depth associations · means across initializations
ModelTime ρRNA depth |ρ|ATAC depth |ρ|
Upstream Decipher0.4250.0300.184
RNA-only ablation0.5260.0980.141
RNA + ATAC0.0310.0550.379
Normalization + dropout-0.0520.1140.095
MultiVI-0.0640.0950.157
RNA PCA-0.1050.0350.042
ATAC LSI-0.0620.0740.236

Cao et al., Science (2018) · GSE117089 / paired A549 sci-CAR data.

Back to the lab’s sparse-trajectory benchmark

This check uses the lab’s original simulator and geometry metric at five transition-sampling densities. It compares the upstream Decipher architecture with RNA PCA on held-out cells.

Adapted lab simulator: global geometry versus transition density0.480.600.710.820.930.0%2.5%5.0%7.5%10.0%Relative sampling density in transition gapsGeometry Kendall τ

Teal: upstream Decipher architecture · Gray: RNA PCA. Points: three-run means; whiskers: 95% t intervals.

Adapted benchmark, not a reproduction of the published Figure 2 results: 1,000 cells, 50 genes, three dataset seeds, six latent dimensions, 120 epochs, and held-out scoring. The paper used a different training protocol and a broader method comparison. The simulator and scoring source are pinned to the lab repository.

Lab reproducibility repository · Original Decipher paper.

Model extension and portfolio evaluations by Shawn Muhr. MultiVI is the published method of Ashuach et al. (2023); it was a direction I considered for my research. Full protocol and results · Data and code provenance.

These earlier plots test signal prediction, not trajectory accuracy. See the trajectory evaluation for ordering, branching, and real treatment-time comparisons.

MY DECIPHER EXTENSION / RNA + CHROMATIN ACCESSIBILITY
Compare the fitted cell states
Synthetic benchmark

My extension adds chromatin accessibility to a Decipher-based RNA model. Compare three fits on the same 280 simulated paired cells: RNA only, RNA + ATAC, and RNA + ATAC with normalization and modality dropout.

Here ATAC carries stronger information about the simulated program than RNA. These plots show actual fitted coordinates and test scores. The simulation does not establish improvement on patient data.

0.430RNA-only ablation · test R²0.601RNA + ATAC · test R²0.800Normalization + dropout · test R²
01 / WHAT I ADDED
Two observation models, one shared cell state

Swipe diagrams sideways to inspect the full labels.

Observed RNA and ATAC feed separate encoders, a product-of-experts posterior over z, and a two-dimensional v representation. Generative decoders model RNA counts and binary peaks.Observed inputsInferenceGenerative modelRNA counts56 genesRNA encoderlog(1 + counts)ATAC accessibility120 binary peaksATAC encoderaccessible / closedShared z6 latent factorsProduct of expertsv2D stateRNA decoderNegative binomialATAC decoderBernoulli peaksv → z → observationsPaired rows: both likelihoods + encoder-alignment penalty

The extension adds an ATAC encoder and a Bernoulli peak decoder. A product of experts combines observed modalities into z. The guide uses z and encoder features to infer v. The paired benchmark also penalizes disagreement between RNA and ATAC encoders (weight 0.25).

02 / COMPARE THE SAME SIMULATED CELLS
Explore the learned representations

Select a point to follow the same cell across all three maps. Each fit has independent latent axes; movement between maps is not a biological trajectory.

RNA-only ablation
ATAC masked · RNA observation model
RNA-only ablation: 280 simulated cells. Each point is a fitted coordinate from the new run.-1.17-1.65-0.79-0.78-0.400.09-0.010.960.381.83Decipher v₁Decipher v₂
RNA + ATAC
Raw RNA input · no modality dropout
RNA + ATAC: 280 simulated cells. Each point is a fitted coordinate from the new run.-0.47-2.16-0.23-1.380.01-0.590.250.190.490.98Decipher v₁Decipher v₂
Normalization + dropout
Normalization + modality dropout
Normalization + dropout: 280 simulated cells. Each point is a fitted coordinate from the new run.-1.33-2.13-0.69-1.34-0.05-0.550.590.251.231.04Decipher v₁Decipher v₂
-2.742.99 · known simulated program

Simulated cell 1 · training · known program 0.538 · progression 1.963 · 852 RNA counts · 39/120 accessible peaks. Training-fitted readouts: RNA 0.615; RNA + ATAC 0.381; normalization + dropout 0.697.

The RNA-only ablation removes ATAC from the same experimental architecture. The study below also includes an independent fit of the original Decipher model.

03 / QUANTIFY THE DIFFERENCE
Measure recovery of the hidden program

A linear readout maps the two latent coordinates to the known simulated program. The default readout is fitted on the 182 training cells and scored on the same 56 test cells for all three models.

Test program recovery. RNA-only 0.42952499768354, RNA plus ATAC 0.6005778961990882.Test program recovery0.000.250.500.751.00RNA-only ablation0.430RNA + ATAC0.601Normalization + dropout0.800R² · higher is better
56 test cells: known simulated program versus linear readout for all three models.Test program predictions-3.2-3.2-1.5-1.50.10.11.81.83.53.5Known simulated programReadout prediction
RNA-only ablationRNA + ATACNormalization + dropoutDashed diagonal = perfect recovery

RNA-only ablation: 0.430 · RNA + ATAC: 0.601 · Normalization + dropout: 0.800. Linear readout fitted on 182 training cells; R² evaluated on 56 test cells.

Read the exact comparisons and evaluation protocol
New simulation run · September 21, 2026
MetricRNA-only ablationRNA + ATACNormalization + dropoutDirection
Test program recovery0.4295250.6005780.800102Higher is better
Test program error0.6550200.5182760.358758Lower is better
Test RNA count error4.8344994.9893904.985277Lower is better
All-cell program recovery0.3192030.4928840.848548Higher is better

This view uses the first prespecified fresh evaluation pair: data seed 201 and model seed 41. Each fit uses 182 training, 42 validation, and 56 test cells. The linear readout is fitted on training cells only.

The detailed maps use the first prespecified fresh evaluation run (data seed 201, model seed 41). Broader comparisons below use three seed pairs and six signal settings. Earlier experiments are retained separately.

The original saved summary used an all-cell readout. Current test metrics restrict scoring to the test partition. The optional all-cell view is descriptive and is not a generalization result.

04 / INSPECT OPTIMIZATION
Follow the training and validation losses
Normalization + dropout, per-cell training and validation objective over 80 epochs.Normalization + dropout120406080194.4222.8251.3279.7308.2EpochBlue: train · orange: validation

Normalization + dropout · epoch 80/80 · train objective 206.869 per cell · validation objective 242.128 per cell. Returned checkpoint: epoch 80, selected by validation. These are objective values, not accuracy scores.

Observation terms and training-time masks differ across configurations. Compare training with validation within a model; lower raw loss across models does not establish better performance.

Model runs from my experimental Decipher extension. Run provenance. Fresh robustness tests and a separate public paired-data comparison follow. The published Figure 1 remains available in the walkthrough’s reference view.

TESTING THE EXTENSION
Which changes help—and where?
Synthetic benchmark

I tested RNA normalization and modality dropout separately, then compared what the model retains in its 2D display and its six latent factors. Each comparison below uses three fresh simulation runs with the same training, validation, and test splits across methods.

Swipe a plot to see its full width.

Separate the two changes

Same architecture and objective weights; change only normalization and dropout.

Test program recovery · R². Bars show means; dots show individual runs.-0.010.260.530.811.08RNA + ATAC0.683Normalization only0.636Dropout only0.677Normalization + dropout0.725Test program recovery · R²
Compare stronger baselines

Independent original Decipher fit, single-assay controls, and the normalization/dropout extension.

Test program recovery · R². Bars show means; dots show individual runs.-0.010.260.530.811.08Original Decipher0.433RNA-only ablation0.429ATAC-only ablation0.867Normalization + dropout0.725RNA PCA · 2D0.422ATAC LSI · 2D0.886Test program recovery · R²

2D v readout: standard RNA + ATAC 0.683; normalization + dropout 0.725 test R² (+0.042 points). For normalization + dropout, the 6D representation scores 0.828 versus 0.725 in its 2D display. Each value is a mean across three fresh runs.

Normalization

Library-size normalization changes the RNA encoder’s input. The count decoder still models raw RNA counts.

Modality dropout

During training, some paired cells temporarily provide only RNA or only ATAC. This tests how the representation handles missing evidence.

The 2D bottleneck

The same trained model can retain information in six factors that is harder to recover from its 2D display. PCA of those factors provides a second 2D comparison.

View modality-weight selection and full results

Six weight combinations were compared on validation data from separate development simulations. The selected weights were frozen before generating the fresh evaluation runs shown above. The search considered both RNA-favored and ATAC-favored signals.

Validation-only search over ATAC likelihood and encoder-alignment weights.ATAC 0.25 · alignment 00.700 validation R²Mean of six development fitsATAC 1 · alignment 00.913 validation R²Mean of six development fitsATAC 4 · alignment 00.814 validation R²Mean of six development fitsATAC 0.25 · alignment 0.250.763 validation R²Mean of six development fitsATAC 1 · alignment 0.250.920 validation R²Selected before fresh test runsATAC 4 · alignment 0.250.819 validation R²Mean of six development fits

The search selected ATAC weight 1 and alignment weight 0.25, with normalization and 25% modality dropout. Those match the normalization/dropout configuration above. Increasing ATAC weight to 4 did not win the validation comparison.

Test R² · mean and 95% Student-t interval across three matched simulation runs
Model2D v6D z2D PCA of z
RNA-only ablation0.429 [0.426, 0.431]0.442 [0.412, 0.471]0.432 [0.416, 0.447]
ATAC-only ablation0.867 [0.783, 0.951]0.875 [0.793, 0.956]0.872 [0.784, 0.960]
RNA + ATAC0.683 [0.332, 1.033]0.788 [0.572, 1.004]0.750 [0.425, 1.075]
Normalization only0.636 [0.124, 1.147]0.763 [0.476, 1.050]0.752 [0.420, 1.084]
Dropout only0.677 [0.268, 1.085]0.809 [0.668, 0.950]0.786 [0.587, 0.985]
Normalization + dropout0.725 [0.273, 1.176]0.828 [0.710, 0.946]0.832 [0.712, 0.951]
Validation-selected0.725 [0.273, 1.176]0.828 [0.710, 0.946]0.832 [0.712, 0.951]
Original Decipher0.433 [0.424, 0.442]0.432 [0.314, 0.550]0.429 [0.397, 0.461]
RNA PCA · 2D0.422 [0.402, 0.442]——
ATAC LSI · 2D0.886 [0.824, 0.949]——

Dots show individual runs; bars show their mean. The intervals describe variation across three dataset/model seed pairs. They are exploratory and do not measure uncertainty across patients. Original Decipher keeps its upstream architecture; equal epoch budgets do not imply equal parameter counts or compute. PCA and LSI use two components and appear in the 2D comparison only.

Completed model runs from my experimental Decipher extension. Data and run provenance. Simulated programs test model behavior; they are not measured cancer phenotypes.

PAIRED RNA + ATAC / PUBLIC DATA
A real-data comparison with MultiVI
Measured PBMC data

MultiVI was a direction I considered during my research on combining RNA and chromatin accessibility. Here, I compare the published method with my Decipher extension using public, paired measurements from the same cells.

1,762 cellsTraining + feature selection407 cellsValidation + readout selection542 cellsHeld-out cross-assay tests

The 10x Genomics dataset contains 2,711 PBMC nuclei from one healthy donor. The benchmark uses 1,000 genes and 2,000 peaks selected on training cells. It tests technical transfer between assays, not cancer progression or performance on new patients.

Swipe a plot to see its full width.

ATAC → RNA · RMSE (lower is better). Bars show means; dots show individual runs.-0.010.320.661.001.33RNA + ATAC1.211Normalization + dropout1.176MultiVI1.126PCA / LSI1.234Promoter activity1.191Training mean1.234ATAC → RNA · RMSE (lower is better)

RNA + ATAC: 1.2112 · Normalization + dropout: 1.1758 · MultiVI: 1.1264 · PCA / LSI: 1.2337 · Promoter activity: 1.1907 · Training mean: 1.2341. Neural dots show three initializations on the same cell split; baselines are deterministic. These are cross-assay readout results, not native decoder scores.

EXPLORE THE HELD-OUT CELLS
Observed expression and cross-assay predictions

The map projects joint latent factors into two dimensions using PCA fitted on training cells. The second plot tests a different task: predict RNA from ATAC alone. Select a cell to connect its position, measured expression, and prediction.

Joint representation · PCA display
PC1 of joint z · training-fitted PCA versus PC2 of joint z; 542 held-out measured cells.-6.5-4.00.6-2.17.6-0.314.71.521.83.4PC1 of joint z · training-fitted PCAPC2 of joint z
ATAC-only input → RNA readout
Observed RNA · log1p(panel 10k) versus Predicted RNA from ATAC; 542 held-out measured cells.-0.9-0.90.80.82.42.44.14.15.75.7Observed RNA · log1p(panel 10k)Predicted RNA from ATAC
05.22 · measured NKG7 expression · log1p(panel 10k)

Test cell 1 of 542 · NKG7 observed 0.000; predicted from ATAC 0.603 · 1375 accessible peaks in the selected panel. Normalization + dropout, first prespecified initialization. The map uses both assays; the prediction uses ATAC alone. Axes are fitted independently for each model.

Methods, regulatory links, and interpretation

All methods use the same cells, feature panel, and train/validation/test split. The neural comparison uses three initialization seeds and an 80-epoch budget, restoring the lowest validation objective. Cross-assay prediction uses the same ridge-readout procedure on six-dimensional assay representations; the hidden assay is zeroed before inference. Readouts fit training cells only and select regularization on validation cells. These are readout benchmarks, not a comparison of native decoder likelihoods.

The selected feature panel contains 245 promoter–gene annotations. I used these links in the promoter-activity comparison instead of assuming RNA and ATAC align simply because their latent dimensions match.

Promoter activity uses the dataset’s genomic annotations to connect selected peaks to genes, then compresses activity to six training-fitted principal components. This is a proximity-based baseline, not proof of regulation. The PCA/LSI baseline uses six components per assay. Matching scores evaluate whether RNA and ATAC representations retrieve the same held-out barcode; no cell-type labels are inferred.

MultiVI: Ashuach et al., Nature Methods (2023), implemented with scvi-tools 1.4.3. For separate RNA and ATAC libraries, GLUE provides a published example of regulatory-graph guidance. This benchmark evaluates paired data and a promoter-activity baseline; it does not establish alignment of unpaired cancer libraries.

Public PBMC test results · means across three neural initializations; deterministic baselines run once
MethodRNA RMSE ↓ATAC BCE ↓ATAC AP ↑FOSCTTM ↓
RNA + ATAC1.21120.66370.67150.4579
Normalization + dropout1.17580.66550.66270.3691
MultiVI1.12640.66690.65980.2369
PCA / LSI1.23370.66310.6690—
Promoter activity1.19070.66310.6690—
Training mean1.23410.67150.6484—

Data: 10x Genomics, paired PBMC 3k, Cell Ranger ARC 2.0.0 · CC BY 4.0. Model comparisons were run for this portfolio; they are separate from the lab’s published results. Provenance.

Earlier robustness controls: shuffled ATAC, feature balance, and checkpoint selection
DECIPHER / TESTS + ABLATIONS
Testing what ATAC adds
Synthetic benchmark · September 21

These experiments test the extension across complementary signals, RNA-dominant signals, a null program, sparse ATAC, variable depth, and missing modalities. Each setting has three matched dataset/model seed pairs. Every fit uses 182 training cells, 42 validation cells for checkpoint selection, and 56 test cells that stay out of fitting and selection.

Complementary ATAC · Joint · alignment 0.25: mean test R² 0.508, across 3 seed pairs. Paired change versus RNA only: +0.164; 95% interval [-0.076, 0.404].

Test recovery across repeated fits

Dots are individual runs; the diamond is their mean. Whiskers show an exploratory 95% Student-t interval across three seed pairs. Wide intervals reflect limited replication. Negative R² means the readout is worse than predicting the test-set mean.

Repeated test R squared for Complementary ATAC. Dots are runs; diamonds are means; whiskers are exploratory intervals.ConfigurationMean R²-0.160.140.430.731.031.32RNA onlyData 42 / model 19: 0.362341Data 43 / model 20: 0.343890Data 44 / model 21: 0.3253160.344ATAC onlyData 42 / model 19: 0.906391Data 43 / model 20: 0.879678Data 44 / model 21: 0.9030380.896Joint · no alignmentData 42 / model 19: 0.853249Data 43 / model 20: 0.402038Data 44 / model 21: 0.7690390.675Joint · alignment 0.25Data 42 / model 19: 0.533452Data 43 / model 20: 0.408331Data 44 / model 21: 0.5827580.508Shuffled ATACData 42 / model 19: 0.273963Data 43 / model 20: 0.334234Data 44 / model 21: 0.3095710.306Per-feature scalingData 42 / model 19: 0.088258Data 43 / model 20: 0.024217Data 44 / model 21: 0.1909210.101Normalized RNA + dropoutData 42 / model 19: 0.880792Data 43 / model 20: 0.675596Data 44 / model 21: 0.9115780.823Joint · final epochData 42 / model 19: 0.612415Data 43 / model 20: 0.408331Data 44 / model 21: 0.5827580.535RNA PCAData 42 / model 19: 0.327408Data 43 / model 20: 0.331253Data 44 / model 21: 0.3172100.325ATAC LSIData 42 / model 19: 0.886468Data 43 / model 20: 0.884175Data 44 / model 21: 0.8996220.890Test R² · higher is better
Inspect the 56 test predictions
Known simulated program versus selected model test predictions.-2.2-2.2-1.1-1.1-0.1-0.11.01.02.12.1Known -1.140 · predicted -1.169Known -0.561 · predicted 0.274Known 0.156 · predicted -1.005Known 0.090 · predicted 0.745Known 0.278 · predicted 0.508Known 1.088 · predicted 0.705Known 0.141 · predicted 0.301Known -0.402 · predicted -0.506Known 1.301 · predicted 0.850Known -0.333 · predicted -0.103Known 0.885 · predicted 0.612Known -2.012 · predicted -0.184Known -0.983 · predicted -1.710Known 1.672 · predicted 0.985Known 0.187 · predicted 0.503Known -0.515 · predicted -0.717Known -0.207 · predicted 0.405Known 1.919 · predicted 0.756Known 1.676 · predicted 0.828Known 0.608 · predicted 0.592Known -1.780 · predicted -0.340Known 0.545 · predicted 0.627Known 1.448 · predicted 0.716Known -0.056 · predicted 0.444Known -0.201 · predicted -0.840Known -0.081 · predicted -0.027Known -0.319 · predicted -1.081Known 0.346 · predicted 0.604Known -0.205 · predicted -1.499Known 0.702 · predicted 0.271Known 1.698 · predicted 0.883Known 0.699 · predicted 0.726Known -0.123 · predicted 0.521Known -0.771 · predicted -0.257Known -1.902 · predicted -1.493Known 0.161 · predicted -0.706Known 0.626 · predicted 0.680Known -0.718 · predicted -0.330Known -0.530 · predicted -1.121Known 0.058 · predicted 0.289Known -0.634 · predicted -0.186Known -0.384 · predicted -1.000Known -0.225 · predicted -0.519Known -0.112 · predicted -0.090Known 0.540 · predicted 0.650Known 0.687 · predicted 0.774Known 0.849 · predicted 0.705Known 1.525 · predicted 0.670Known 0.364 · predicted 0.810Known 1.116 · predicted -0.085Known -0.202 · predicted -0.085Known -2.030 · predicted -1.793Known -1.401 · predicted -1.963Known 0.825 · predicted 0.661Known -0.642 · predicted -1.263Known -0.385 · predicted 0.191Known simulated programTrain-fitted readout

Joint · alignment 0.25 · data seed 42, model seed 19 · test R² 0.533 · MAE 0.503. Returned epoch 77/80. Dashed line: perfect recovery.

What changed in the code

Separate test data. Patient partitions are frozen before selecting ATAC peaks. Feature selection and linear readouts use training rows only.

Recoverable fits. Checkpoints save neural weights, RNA dispersion, feature names, splits, and histories. Validation selects a checkpoint; test scores do not.

Experimental options. RNA input normalization, modality dropout, and per-feature loss scaling are tested as separate configurations. They are not assumed to help.

Controls. ATAC-only, no-alignment, shuffled-pairing, final-epoch, RNA PCA, and ATAC LSI comparisons test alternative explanations. Shuffling stays within each partition.

Across simulation settings

Mean test R² over three seed pairs. Select a tile to inspect that setting and configuration. Blank cells mean that configuration was not run for the missing-modality design.

Mean test R squared for all six simulation settings and ten configurations.RNAATACNo align.JointShuffleScaledNorm/dropFinalPCALSIComplementary ATACComplementary ATAC · RNA only · mean test R² 0.3438490.34Complementary ATAC · ATAC only · mean test R² 0.8963690.90Complementary ATAC · Joint · no alignment · mean test R² 0.6747760.67Complementary ATAC · Joint · alignment 0.25 · mean test R² 0.5081800.51Complementary ATAC · Shuffled ATAC · mean test R² 0.3059230.31Complementary ATAC · Per-feature scaling · mean test R² 0.1011320.10Complementary ATAC · Normalized RNA + dropout · mean test R² 0.8226550.82Complementary ATAC · Joint · final epoch · mean test R² 0.5345010.53Complementary ATAC · RNA PCA · mean test R² 0.3252900.33Complementary ATAC · ATAC LSI · mean test R² 0.8900880.89RNA-dominantRNA-dominant · RNA only · mean test R² 0.9766530.98RNA-dominant · ATAC only · mean test R² 0.3079110.31RNA-dominant · Joint · no alignment · mean test R² 0.9656510.97RNA-dominant · Joint · alignment 0.25 · mean test R² 0.9653900.97RNA-dominant · Shuffled ATAC · mean test R² 0.9616910.96RNA-dominant · Per-feature scaling · mean test R² 0.2756310.28RNA-dominant · Normalized RNA + dropout · mean test R² 0.9682260.97RNA-dominant · Joint · final epoch · mean test R² 0.9636180.96RNA-dominant · RNA PCA · mean test R² 0.8228820.82RNA-dominant · ATAC LSI · mean test R² 0.2839810.28Null programNull program · RNA only · mean test R² 0.0037630.00Null program · ATAC only · mean test R² -0.002785-0.00Null program · Joint · no alignment · mean test R² -0.004321-0.00Null program · Joint · alignment 0.25 · mean test R² 0.0104730.01Null program · Shuffled ATAC · mean test R² 0.0047200.00Null program · Per-feature scaling · mean test R² -0.000545-0.00Null program · Normalized RNA + dropout · mean test R² 0.0035810.00Null program · Joint · final epoch · mean test R² 0.0109140.01Null program · RNA PCA · mean test R² 0.0089810.01Null program · ATAC LSI · mean test R² -0.041474-0.04Sparse ATACSparse ATAC · RNA only · mean test R² 0.3438490.34Sparse ATAC · ATAC only · mean test R² 0.0188850.02Sparse ATAC · Joint · no alignment · mean test R² 0.3506510.35Sparse ATAC · Joint · alignment 0.25 · mean test R² 0.3642700.36Sparse ATAC · Shuffled ATAC · mean test R² 0.3294110.33Sparse ATAC · Per-feature scaling · mean test R² 0.0222050.02Sparse ATAC · Normalized RNA + dropout · mean test R² 0.3944690.39Sparse ATAC · Joint · final epoch · mean test R² 0.3643700.36Sparse ATAC · RNA PCA · mean test R² 0.3252900.33Sparse ATAC · ATAC LSI · mean test R² 0.0111960.01Variable depthVariable depth · RNA only · mean test R² 0.3137410.31Variable depth · ATAC only · mean test R² 0.8544140.85Variable depth · Joint · no alignment · mean test R² 0.4600390.46Variable depth · Joint · alignment 0.25 · mean test R² 0.5202450.52Variable depth · Shuffled ATAC · mean test R² 0.3059070.31Variable depth · Per-feature scaling · mean test R² 0.2201910.22Variable depth · Normalized RNA + dropout · mean test R² 0.5241800.52Variable depth · Joint · final epoch · mean test R² 0.5231410.52Variable depth · RNA PCA · mean test R² 0.3200000.32Variable depth · ATAC LSI · mean test R² 0.4616130.46Missing modalities——Missing modalities · Joint · no alignment · mean test R² 0.5848750.58Missing modalities · Joint · alignment 0.25 · mean test R² 0.5964560.60—Missing modalities · Per-feature scaling · mean test R² 0.0593970.06Missing modalities · Normalized RNA + dropout · mean test R² 0.5321480.53Missing modalities · Joint · final epoch · mean test R² 0.5964560.60——Below zeroNear zeroNear oneNot runRNA / ATAC = single-modality neural ablations · PCA / LSI = two-coordinate linear baselines
Exact scores, evaluation protocol, and limits
Selected setting · mean and 95% interval over seed pairs
ConfigurationMean test R²95% intervalPaired change vs RNA
RNA only0.3438490.297861 to 0.3898370.000000
ATAC only0.8963690.860220 to 0.9325180.552520
Joint · no alignment0.6747760.078779 to 1.2707730.330927
Joint · alignment 0.250.5081800.284812 to 0.7315490.164331
Shuffled ATAC0.3059230.230652 to 0.381194-0.037926
Per-feature scaling0.101132-0.107770 to 0.310034-0.242717
Normalized RNA + dropout0.8226550.503979 to 1.1413310.478806
Joint · final epoch0.5345010.260579 to 0.8084240.190652
RNA PCA0.3252900.307263 to 0.343317-0.018559
ATAC LSI0.8900880.869381 to 0.9107950.546239

Each neural model has an 80-epoch budget. The final-epoch control returns epoch 80; other neural models restore the lowest validation objective. The linear readout is fitted on training coordinates only. PCA components and LSI inverse-document frequencies are also fitted on training cells only. All methods use two readout coordinates.

These are exploratory synthetic comparisons, with three matched seed pairs and no multiple-comparison correction. The RNA-dominant and null settings test whether the gains depend on the simulated signal. The missing-modality setting retains valid single-modality cells; single-modality baselines and shuffled pairing are omitted there. Normalization plus dropout is a combined intervention, so this grid does not separate their individual effects.

Independent upstream Decipher, MultiVI/GLUE, patient-level outcomes, and biological trajectory validation remain future comparisons. The current tests do not establish improved cancer prediction or valid alignment of unpaired patient libraries.

Numerical outputs from run_ablation_benchmark.py in my experimental fork. Code and run provenance ↗. Each point is an executed model or baseline result; no paper image was used to generate these values.

Explore cancer cell states and marker genes
Saved model output

These views use the Azizi Lab’s saved Decipher coordinates and measured RNA counts. Compare marker genes, inspect individual cells, or read expression across cell populations.

DECIPHER TUTORIAL / COORDINATED FEATURE MAPS
Gene expression on the Decipher map

The lab’s tutorial plots these six genes in a three-column layout. Here, selecting a cell marks it in every panel so you can compare its measured expression.

Swipe when enlarged. Fit for an overview.
Six coordinated gene-expression feature maps, following the Decipher lab tutorial. Identical saved cell coordinates in every panel.NPM1p99 4.77v₁v₂0PROM1p99 1.93v₁v₂0AVPp99 3.97v₁v₂0CD34p99 2.57v₁v₂0MPOp99 5.33v₁v₂0LYZp99 6.97v₁v₂0

AML1 · blast0 · source row 1. NPM1 25 · PROM1 2 · AVP 0 · CD34 0 · MPO 0 · LYZ 2 raw counts.

2,000 cells per map; a fixed 2,000-cell subset before filtering (every ninth source row). Each gene has its own 99th-percentile color limit, held fixed across conditions. All maps share the same axes; rings identify the same cell.

Plot layout and marker set: Azizi Lab’s Decipher tutorial, dc.pl.decipher ↗. Colors use measured log1p normalized RNA counts; no gene predictions are generated.

Enlarge, then swipe to inspect.
Actual saved Decipher coordinates from the lab tutorial dataset. Color shows source cell annotations or measured gene expression.Decipher · saved model coordinates-2-1012-1.5-0.50.51.5Latent coordinate v₁Latent coordinate v₂
blast0blast1blast2blast3eryimmaturelymphomep

6,000 cells visible from a fixed 6,000-cell display sample of 18,000 source cells. Colors use the source cell-type annotations.

Enlarge, then swipe to inspect.
AVP mean measured expression by cell type, across all 18,000 source cells.AVP · mean measured expression by cell type0.06blast00.05blast10.00blast20.00blast30.18ery1.28immature0.17lympho0.30mepMean log1p normalized counts · all 18,000 source cells
Swipe when enlarged. Fit for an overview.
Ten saved Decipher factors for the selected cell. Negative and positive values are coordinates, not decreases or increases in expression.Selected cell · ten learned factors z4.80.0-4.8z12.51z2-2.50z33.86z4-2.08z54.78z62.92z74.82z8-3.69z9-2.96z10-2.28

AML1 · blast0 · source row 1. Select a factor bar or choose a latent factor under Color by to locate its values on the cell map. The axis fits this cell’s factor range.

The profile summarizes all 18,000 source cells. The scatterplot shows every third row (6,000 cells); filtering does not retrain or move the model.

RNA EXPRESSION / ALL 18,000 CELLS
Marker expression across populations

A standard single-cell dot plot: dot area shows the fraction of cells with detected RNA; color shows mean expression. Switch to the heatmap for numeric tiles. Both summaries use every source cell.

Swipe when enlarged. Fit for an overview.
Measured gene expression across cell annotations. Mean log1p normalized counts.Marker genes · mean expression + detectionAVPMPOCD68HOXA9CD34LYZNPM1PROM1blast0blast0 · AVP · 2701 cells · 0.064blast0 · MPO · 2701 cells · 0.321blast0 · CD68 · 2701 cells · 0.674blast0 · HOXA9 · 2701 cells · 0.908blast0 · CD34 · 2701 cells · 0.025blast0 · LYZ · 2701 cells · 0.770blast0 · NPM1 · 2701 cells · 3.145blast0 · PROM1 · 2701 cells · 0.2632,701blast1blast1 · AVP · 549 cells · 0.051blast1 · MPO · 549 cells · 1.654blast1 · CD68 · 549 cells · 0.419blast1 · HOXA9 · 549 cells · 0.814blast1 · CD34 · 549 cells · 0.015blast1 · LYZ · 549 cells · 1.030blast1 · NPM1 · 549 cells · 3.304blast1 · PROM1 · 549 cells · 0.193549blast2blast2 · AVP · 2645 cells · 0.002blast2 · MPO · 2645 cells · 0.184blast2 · CD68 · 2645 cells · 0.874blast2 · HOXA9 · 2645 cells · 0.887blast2 · CD34 · 2645 cells · 0.000blast2 · LYZ · 2645 cells · 6.299blast2 · NPM1 · 2645 cells · 2.492blast2 · PROM1 · 2645 cells · 0.0012,645blast3blast3 · AVP · 4985 cells · 0.002blast3 · MPO · 4985 cells · 0.029blast3 · CD68 · 4985 cells · 1.811blast3 · HOXA9 · 4985 cells · 0.253blast3 · CD34 · 4985 cells · 0.001blast3 · LYZ · 4985 cells · 5.773blast3 · NPM1 · 4985 cells · 1.017blast3 · PROM1 · 4985 cells · 0.0004,985eryery · AVP · 171 cells · 0.183ery · MPO · 171 cells · 0.096ery · CD68 · 171 cells · 0.264ery · HOXA9 · 171 cells · 0.380ery · CD34 · 171 cells · 0.554ery · LYZ · 171 cells · 0.722ery · NPM1 · 171 cells · 3.835ery · PROM1 · 171 cells · 0.056171immatureimmature · AVP · 5747 cells · 1.279immature · MPO · 5747 cells · 2.226immature · CD68 · 5747 cells · 0.170immature · HOXA9 · 5747 cells · 0.260immature · CD34 · 5747 cells · 0.759immature · LYZ · 5747 cells · 1.339immature · NPM1 · 5747 cells · 3.894immature · PROM1 · 5747 cells · 0.2775,747lympholympho · AVP · 336 cells · 0.167lympho · MPO · 336 cells · 0.704lympho · CD68 · 336 cells · 0.018lympho · HOXA9 · 336 cells · 0.066lympho · CD34 · 336 cells · 0.605lympho · LYZ · 336 cells · 0.193lympho · NPM1 · 336 cells · 3.161lympho · PROM1 · 336 cells · 0.030336mepmep · AVP · 866 cells · 0.299mep · MPO · 866 cells · 1.172mep · CD68 · 866 cells · 0.076mep · HOXA9 · 866 cells · 0.254mep · CD34 · 866 cells · 0.726mep · LYZ · 866 cells · 0.548mep · NPM1 · 866 cells · 4.182mep · PROM1 · 866 cells · 0.069866n06.3010%50%100%Color: mean expression · Area: cells with detected RNA× no source cells · hollow dot: 0% detected

Both conditions · blast0 · AVP: 0.064 mean log1p normalized counts. n = 2,701. Detected in 4.4% of cells.

Dot-plot encoding follows Scanpy’s single-cell plotting convention ↗; this summary is calculated from the lab’s public tutorial data.

Model and expression details

Decipher’s generative hierarchy maps a two-dimensional state v through higher-dimensional factors z to gene counts x, using a negative-binomial count likelihood. Both v and the ten z factors shown here come directly from the saved tutorial model. Factor colors use a zero-centered scale clipped at the 99th percentile of absolute values for that factor; the inspector retains the unclipped values. The website does not refit the model.

Gene colors use log1p(10,000 × gene count / total counts across the 3,130 provided genes), clipped at the full dataset’s 99th percentile for each gene. The inspector shows the original counts. Expression profiles are means of the same normalized values, grouped by source annotations. No cell barcodes or mutation metadata are displayed.

Azizi Lab tutorial dataset ↗ · Published model implementation ↗ · Decipher paper ↗. Gene colors are measured expression, not reconstructed gene predictions.

Paper figures & project notesRead the Decipher paper
03 / DUVALL LAB · MOSQUITO NEUROBIOLOGYPublished data

Mosquito neurobiology

In the Duvall Lab, I developed an assay to study Aedes aegypti biology. Figure 2 in this study connects NPYLR7 loss to egg provisioning and hatch rate.

My role: Mosquito Neurobiology Amgen Scholar · May–August 2023

NPYLR7, egg provisioning, and hatch rate
Published measurements

Figure 2 from the Duvall Lab study I worked on. Each point below comes directly from the paper’s source-data workbook. Switch measurements to compare body mass, eggs, hatch rates, and protein content.

Enlarge, then swipe to inspect.
C · Egg viability. Published observations grouped by genotype; horizontal bars show medians.C · Egg viabilityEgg viability (% hatch)020406080100Wild type · 90 · source A!U5Wild type · 95.6 · source A!U6Wild type · 87.88 · source A!U7Wild type · 67 · source A!U8Wild type · 81.69 · source A!U9Wild type · 86.55 · source A!U10Wild type · 94.59 · source A!U11Wild type · 88.16 · source A!U12Wild type · 70.83 · source A!U13Wild typen = 9 · median 87.88npylr7 QF2/+ · 87.91 · source A!V5npylr7 QF2/+ · 85.26 · source A!V6npylr7 QF2/+ · 72 · source A!V7npylr7 QF2/+ · 98.33 · source A!V8npylr7 QF2/+ · 94.51 · source A!V9npylr7 QF2/+ · 71.43 · source A!V10npylr7 QF2/+ · 98.85 · source A!V11npylr7 QF2/+ · 97.83 · source A!V12npylr7 QF2/+ · 97.18 · source A!V13npylr7 QF2/+ · 88.24 · source A!V14npylr7 QF2/+ · 79.31 · source A!V15npylr7 QF2/+ · 100 · source A!V16QF2/+n = 12 · median 91.375npylr7 QF2/QF2 · 12.5 · source A!W5npylr7 QF2/QF2 · 70 · source A!W6npylr7 QF2/QF2 · 22.9 · source A!W7npylr7 QF2/QF2 · 70.94 · source A!W8npylr7 QF2/QF2 · 35.11 · source A!W9npylr7 QF2/QF2 · 51 · source A!W10npylr7 QF2/QF2 · 58.73 · source A!W11npylr7 QF2/QF2 · 42.53 · source A!W12npylr7 QF2/QF2 · 81.16 · source A!W13npylr7 QF2/QF2 · 47.54 · source A!W14npylr7 QF2/QF2 · 77.78 · source A!W15npylr7 QF2/QF2 · 80 · source A!W16npylr7 QF2/QF2 · 0 · source A!W17QF2/QF2n = 13 · median 51P = 0.7901P = 0.0003
Wild typenpylr7 QF2/+npylr7 QF2/QF2

Dots: source measurements. Horizontal bars: medians. Horizontal spacing only separates overlapping dots.

Wild type: n = 9, median 87.88 · npylr7 QF2/+: n = 12, median 91.375 · npylr7 QF2/QF2: n = 13, median 51

Select a point to inspect its value and source cell, or open the measurements table.

Inspect the source measurements
Egg viability (% hatch)
GenotypeValueWorkbook cell
Wild type90A!U5
Wild type95.6A!U6
Wild type87.88A!U7
Wild type67A!U8
Wild type81.69A!U9
Wild type86.55A!U10
Wild type94.59A!U11
Wild type88.16A!U12
Wild type70.83A!U13
npylr7 QF2/+87.91A!V5
npylr7 QF2/+85.26A!V6
npylr7 QF2/+72A!V7
npylr7 QF2/+98.33A!V8
npylr7 QF2/+94.51A!V9
npylr7 QF2/+71.43A!V10
npylr7 QF2/+98.85A!V11
npylr7 QF2/+97.83A!V12
npylr7 QF2/+97.18A!V13
npylr7 QF2/+88.24A!V14
npylr7 QF2/+79.31A!V15
npylr7 QF2/+100A!V16
npylr7 QF2/QF212.5A!W5
npylr7 QF2/QF270A!W6
npylr7 QF2/QF222.9A!W7
npylr7 QF2/QF270.94A!W8
npylr7 QF2/QF235.11A!W9
npylr7 QF2/QF251A!W10
npylr7 QF2/QF258.73A!W11
npylr7 QF2/QF242.53A!W12
npylr7 QF2/QF281.16A!W13
npylr7 QF2/QF247.54A!W14
npylr7 QF2/QF277.78A!W15
npylr7 QF2/QF280A!W16
npylr7 QF2/QF20A!W17
Statistical and source notes

The original figure shows medians and 95% confidence intervals. This redraw shows the individual source values and medians; it does not reconstruct those intervals. Adjusted P values are copied from Data S1, sheet A, rather than recalculated when a group is highlighted.

Sample sizes count the numeric entries in the workbook. Some workbook n labels differ from their filled rows. The caption and workbook also differ in the named tests for panels A and C; the displayed P values follow the workbook. Every measurement remains traceable to its source cell.

Greppi, Frank, Saltz & Duvall (2026), Current Biology · Figure 2 and Data S1, sheet A ↗. Original figure retained with author attribution. My connection to this figure is from my work in the Duvall Lab.

Original Figure 2 & paper
Original Figure 2 showing wild-type, heterozygous, and homozygous npylr7 mosquito measurements.View full size ↗
Figure 2 · Greppi, Frank, Saltz & Duvall (2026). Unmodified publisher figure. Original paper ↗
03 / COLORADO SCHOOL OF MINES

Research at Mines

04 / HUA WANG’S LAB · NEUROINFORMATICSData preparation + code review

SNP data preparation for Alzheimer’s research

I supported Alzheimer’s disease research in Hua Wang’s lab by extracting and cleaning SNP (single nucleotide polymorphism) data and helping review research code.

My role: Machine Learning Neuroinformatics Researcher · May–September 2022

WHERE I CONTRIBUTED
01 / Data extraction02 / SNP data cleaning03 / Code review

The interactive models below explain related research from the lab. Their methods and reported results belong to the paper’s authors; they describe the research context for my supporting role.

RELATED LAB RESEARCH / IMAGING + GENETICS
From repeated scans to memory predictions
Research context

Follow how a longitudinal model brings MRI measurements, genetic variants, and observed cognitive scores into a shared representation. Then compare the published prediction errors and inspect the features the model weighted.

Based on Seo, Brand & Wang (2024), related work from Hua Wang’s lab; not a confirmed publication of my 2022 project. My lab contribution focused on SNP data preparation and code review.

01 / Keep the available visits

The method learns from each participant’s available imaging records, even when record counts differ. The timeline is a schematic; it contains no participant measurements.

Swipe diagrams sideways to see the full plot.

a
Repeated visits → one representation
Method diagram · Figure 1
Schematic imaging visits at baseline, 6, 12, and 24 months. The 24-month visit is missing; the last record is at 12 months. A learned projection produces a fixed-length vector.One schematic participantRepeated MRI features · no measurement valuesBaselineEarlier: Xᵢ6 monthsEarlier: Xᵢ12 monthsLast: xᵢ24 monthsMissingvisitLearn Wᵢ from available recordszᵢ = Wᵢᵀ xᵢ3 available visits → fixed-length enriched vectorTiles indicate feature vectors; no fitted values shown.

Last observed visit: 12 months. Earlier records help learn Wᵢ; the last record xᵢ is projected to zᵢ. The dimension of zᵢ stays fixed. This switch does not simulate an MRI or alter the published benchmark.

b
Couple imaging, genetics, and labels
Model structure · Figure 2
Conceptual factorization of genetic, enriched imaging, and observed clinical-score matrices through shared participant factors. Colored tiles are symbolic, not numerical model outputs.Genetics · staticX_SNP≈H₀×GEnriched MRIZ≈H₁×GObserved scoresYₗ≈H₂×GₗShared participant columns

Shared participant factors connect static genetics, enriched imaging, and available clinical scores. Matching purple columns indicate the same participants, not fitted numbers.

WHAT DOES THE MODEL WEIGHT?
Inspect both sides of the representation

Imaging weights locate selected brain regions. Genetic weights can be inspected as individual variants or groups of variants.

c
Brain-region weights
Original image · Figure 4
Published brain-region weight maps for FreeSurfer on the left and voxel-based morphometry on the right; darker areas carry larger model weights.
Darker shading = larger model weightView complete figure ↗

Four regions identified for each MRI representation

  • FS · Right caudate
  • FS · Brodmann area 24
  • FS · Left thalamus
  • FS · Left caudate
  • VBM · Left hippocampus
  • VBM · Left amygdala
  • VBM · Left thalamus
  • VBM · Right medial orbitofrontal cortex

FS and VBM are two ways to extract measurements from MRI. This is the paper’s weight map; numeric region weights are not supplied here. Weight is not a measure of tissue damage.

d
Variants → gene groups
Published weights · Figures 5 & 6
Published top-ten SNP weights and group membership. Selected rs10779339, CR1, approximate weight 0.1195.SNP weightGene group0.000.050.10rs10779339rs4343rs4353rs4311rs4309rs4329rs4267385rs8066276rs4305rs12451328CR1mean ≈ 0.09391 shown / 15 in groupACEmean ≈ 0.09889 shown / 11 in groupZero-based weight axis

rs10779339 → CR1: individual weight ≈ 0.1195. The CR1 group mean is ≈ 0.0939 across 15 SNPs. These are different summaries of the same feature set.

Links show group membership, not biological interactions. Only the ten displayed SNPs from Figure 5 appear here. Group means in Figure 6 include additional variants.

DOES ENRICHMENT HELP? / PUBLISHED FIGURE 3
Compare the same model across input combinations

Each pair compares original and enriched features. Left is lower prediction error. Change the regressor, then select an input combination to follow it across three memory-test outcomes.

Original featuresEnriched features↑ Error increased

Swipe diagrams sideways to see the full plot.

RAVLT total. Published original and enriched RMSE for SVR. Lower is better.Total learningRAVLT · SVR0.00.10.20.30.40.5SNP + FS + VBM↓ 25.60%SNP + FS↓ 0.26%SNP + VBM↓ 2.52%SNP↑ 0.10%RMSE · lower is better
RAVLT 30-minute recall. Published original and enriched RMSE for SVR. Lower is better.30-minute recallRAVLT · SVR0.00.10.20.30.40.5SNP + FS + VBM↓ 16.15%SNP + FS↓ 1.76%SNP + VBM↓ 5.95%SNP↑ 0.84%RMSE · lower is better
RAVLT recognition. Published original and enriched RMSE for SVR. Lower is better.RecognitionRAVLT · SVR0.00.10.20.30.40.5SNP + FS + VBM↓ 33.03%SNP + FS↓ 11.96%SNP + VBM↑ 1.10%SNP↑ 0.08%RMSE · lower is better

SVR · SNP + FS + VBM · RAVLT total: original RMSE ≈ 0.244 → enriched RMSE ≈ 0.182. The paper reports 25.60% lower error.

RMSE means root mean squared error. Values and SDs are approximately digitized from Figure 3; percentage changes use the paper’s printed labels. Each panel uses a zero-based RMSE axis. The missing-visit diagram above does not change these published results or run a model.

Read the values in a table
Published comparisons for support vector regression
OutcomeInputsOriginal RMSE ± SDEnriched RMSE ± SDError change
RAVLT totalSNP + FS + VBM0.244 ± 0.0410.182 ± 0.03325.60% lower
RAVLT 30-minute recallSNP + FS + VBM0.327 ± 0.0670.274 ± 0.03516.15% lower
RAVLT recognitionSNP + FS + VBM0.366 ± 0.0810.245 ± 0.06133.03% lower
RAVLT totalSNP + FS0.190 ± 0.0410.189 ± 0.0480.26% lower
RAVLT 30-minute recallSNP + FS0.262 ± 0.0450.257 ± 0.0471.76% lower
RAVLT recognitionSNP + FS0.268 ± 0.0940.236 ± 0.07411.96% lower
RAVLT totalSNP + VBM0.159 ± 0.0420.155 ± 0.0352.52% lower
RAVLT 30-minute recallSNP + VBM0.302 ± 0.0650.284 ± 0.0845.95% lower
RAVLT recognitionSNP + VBM0.300 ± 0.1030.303 ± 0.0821.10% higher
RAVLT totalSNP0.206 ± 0.0710.206 ± 0.0650.10% higher
RAVLT 30-minute recallSNP0.273 ± 0.0880.276 ± 0.0910.84% higher
RAVLT recognitionSNP0.390 ± 0.1240.390 ± 0.1310.08% higher

Method diagrams adapted from Figures 1–2; original brain image from Figure 4; interactive results from Figures 3, 5–6. Seo, Brand & Wang (2024), BMC Medical Informatics and Decision Making ↗ · CC BY 4.0. Diagrams explain the method; results reproduce the related paper, not participant-level records or new predictions.

Explore imaging–genetic model results
Published lab benchmark

Inspect the genetic feature weights and prediction comparisons published by Seo, Brand & Wang (2024), from Hua Wang’s lab. These are interactive redraws of the paper’s results.

PUBLISHED FIGURES 5 & 6 / FEATURE WEIGHTS
From gene groups to individual variants

The paper ranks genetic features by learned model weight. Select a group to locate its variants in the displayed SNP ranking.

Swipe when enlarged. Fit for an overview.
AlzGene groups · Figure 6AlzGene groups · Figure 60.000.030.060.090.12ACE≈0.0988ACE: approximate weight 0.09875, 11 SNPs, SD approximately 0.00538APOE≈0.0956APOE: approximate weight 0.09556, 3 SNPs, SD approximately 0.00039CR1≈0.0939CR1: approximate weight 0.09391, 15 SNPs, SD approximately 0.00685SORL1≈0.0939SORL1: approximate weight 0.09390, 68 SNPs, SD approximately 0.00056CALHM1≈0.0924CALHM1: approximate weight 0.09242, 5 SNPs, SD approximately 0.00051THRA≈0.0924THRA: approximate weight 0.09235, 1 SNPs, SD not displayedIL1A≈0.0923IL1A: approximate weight 0.09229, 9 SNPs, SD approximately 0.00070CST3≈0.0923CST3: approximate weight 0.09229, 6 SNPs, SD approximately 0.00019TFAM≈0.0922TFAM: approximate weight 0.09224, 25 SNPs, SD approximately 0.00057IL1B≈0.0922IL1B: approximate weight 0.09223, 14 SNPs, SD approximately 0.00063Learned weight · zero-based axis
Swipe when enlarged. Fit for an overview.
Individual SNPs · Figure 5Individual SNPs · Figure 50.000.030.060.090.12rs10779339≈0.1195rs10779339: approximate weight 0.11949, CR1 grouprs4343≈0.1157rs4343: approximate weight 0.11565, ACE grouprs4353≈0.0981rs4353: approximate weight 0.09813, ACE grouprs4311≈0.0978rs4311: approximate weight 0.09775, ACE grouprs4309≈0.0976rs4309: approximate weight 0.09761, ACE grouprs4329≈0.0976rs4329: approximate weight 0.09757, ACE grouprs4267385≈0.0971rs4267385: approximate weight 0.09711, ACE grouprs8066276≈0.0970rs8066276: approximate weight 0.09699, ACE grouprs4305≈0.0968rs4305: approximate weight 0.09678, ACE grouprs12451328≈0.0967rs12451328: approximate weight 0.09670, ACE groupLearned weight · zero-based axis

Select a gene group to link the two rankings. The paper displays ten SNPs: nine in ACE and one in CR1. Whiskers show variation among SNP weights within each gene group.

Weights and standard deviations are approximate, digitized from the original vector figures. Colors follow the paper’s gene groups. Whiskers show variation among SNP weights within a group—not confidence intervals or variability across validation folds. These are model weights, not association P values or clinical risk scores.

Numeric values and source details
Approximate weights digitized from Figures 5 and 6
FeatureType / groupWeight ≈SD ≈SNP count
ACEAlzGene group0.098750.0053811
APOEAlzGene group0.095560.000393
CR1AlzGene group0.093910.0068515
SORL1AlzGene group0.093900.0005668
CALHM1AlzGene group0.092420.000515
THRAAlzGene group0.09235Not displayed1
IL1AAlzGene group0.092290.000709
CST3AlzGene group0.092290.000196
TFAMAlzGene group0.092240.0005725
IL1BAlzGene group0.092230.0006314
rs10779339CR10.11949Not displayed—
rs4343ACE0.11565Not displayed—
rs4353ACE0.09813Not displayed—
rs4311ACE0.09775Not displayed—
rs4309ACE0.09761Not displayed—
rs4329ACE0.09757Not displayed—
rs4267385ACE0.09711Not displayed—
rs8066276ACE0.09699Not displayed—
rs4305ACE0.09678Not displayed—
rs12451328ACE0.09670Not displayed—

Redrawn from Figure 5 and Figure 6 · Seo, Brand & Wang (2024) · CC BY 4.0. Only features displayed in these figures are included.

Swipe when enlarged. Fit for an overview.
RAVLT total. Approximate RMSE before and after enrichment, SNP + FS + VBM. Lower is better.RAVLT total · SNP + FS + VBM0.00.10.20.30.40.50.6RMSE · lower is better≈0.244SVR · original: RMSE approximately 0.244, SD approximately 0.041.≈0.182SVR · enriched: RMSE approximately 0.182, SD approximately 0.033.SVR25.60% lower error≈0.211Ridge regression · original: RMSE approximately 0.211, SD approximately 0.015.≈0.178Ridge regression · enriched: RMSE approximately 0.178, SD approximately 0.024.Ridge regression15.64% lower error≈0.286CNN · original: RMSE approximately 0.286, SD approximately 0.034.≈0.180CNN · enriched: RMSE approximately 0.180, SD approximately 0.024.CNN36.81% lower error
Original featuresEnriched featuresWhiskers: five-fold standard deviation

RMSE and standard deviations are approximate, digitized from Figure 3 (rounded to 0.001). Percentage changes reproduce the figure’s printed labels.

Swipe when enlarged. Fit for an overview.
Published percent reduction in RMSE for RAVLT total. Positive values mean improvement; negative values mean higher error.Which inputs benefit from enrichment?SVRRidge regressionCNNSNP + FS + VBM+25.60%SNP + FS + VBM · SVR · 25.60% lower RMSE with enrichment.+15.64%SNP + FS + VBM · Ridge regression · 15.64% lower RMSE with enrichment.+36.81%SNP + FS + VBM · CNN · 36.81% lower RMSE with enrichment.SNP + FS+0.26%SNP + FS · SVR · 0.26% lower RMSE with enrichment.-1.29%SNP + FS · Ridge regression · 1.29% higher RMSE with enrichment.+12.80%SNP + FS · CNN · 12.80% lower RMSE with enrichment.SNP + VBM+2.52%SNP + VBM · SVR · 2.52% lower RMSE with enrichment.+4.34%SNP + VBM · Ridge regression · 4.34% lower RMSE with enrichment.+18.88%SNP + VBM · CNN · 18.88% lower RMSE with enrichment.SNP-0.10%SNP · SVR · 0.10% higher RMSE with enrichment.+4.50%SNP · Ridge regression · 4.50% lower RMSE with enrichment.-6.77%SNP · CNN · 6.77% higher RMSE with enrichment.Teal / positive: lower error · Coral / negative: higher error

SVR with SNP + FS + VBM: RAVLT total, RMSE ≈0.244 → ≈0.182. The figure reports 25.60% lower error with enriched features.

Study design and all 36 comparisons

The study uses 412 ADNI participants with imaging at baseline, 6, 12, and 24 months. It removes the 24-month record with 50% probability to evaluate incomplete histories. Shared factors combine genetic variants (SNPs), MRI features (FS and VBM), and available clinical scores before prediction. These are aggregate benchmarks, not individual participant records.

Positive percentages mean lower RMSE after enrichment; negative values mean higher RMSE. The bars and standard deviations are digitized estimates; percentage labels are transcribed directly. Differences should not be read as statistical significance or as effects caused by individual biomarkers.

Figure 3 · approximate RMSE ± SD; reported percent reduction
InputsOutcomeModelOriginal ≈Enriched ≈Reduction
SNP + FS + VBMRAVLT totalSVR0.244 ± 0.0410.182 ± 0.033+25.60%
SNP + FS + VBMRAVLT totalRidge regression0.211 ± 0.0150.178 ± 0.024+15.64%
SNP + FS + VBMRAVLT totalCNN0.286 ± 0.0340.180 ± 0.024+36.81%
SNP + FS + VBMRAVLT 30-minute recallSVR0.327 ± 0.0670.274 ± 0.035+16.15%
SNP + FS + VBMRAVLT 30-minute recallRidge regression0.286 ± 0.0210.265 ± 0.017+7.28%
SNP + FS + VBMRAVLT 30-minute recallCNN0.344 ± 0.0410.270 ± 0.028+21.63%
SNP + FS + VBMRAVLT recognitionSVR0.366 ± 0.0810.245 ± 0.061+33.03%
SNP + FS + VBMRAVLT recognitionRidge regression0.290 ± 0.0480.246 ± 0.055+15.08%
SNP + FS + VBMRAVLT recognitionCNN0.315 ± 0.0650.259 ± 0.035+17.64%
SNP + FSRAVLT totalSVR0.190 ± 0.0410.189 ± 0.048+0.26%
SNP + FSRAVLT totalRidge regression0.178 ± 0.0350.180 ± 0.034-1.29%
SNP + FSRAVLT totalCNN0.215 ± 0.0370.187 ± 0.038+12.80%
SNP + FSRAVLT 30-minute recallSVR0.262 ± 0.0450.257 ± 0.047+1.76%
SNP + FSRAVLT 30-minute recallRidge regression0.280 ± 0.0230.271 ± 0.031+3.11%
SNP + FSRAVLT 30-minute recallCNN0.397 ± 0.0420.264 ± 0.035+33.58%
SNP + FSRAVLT recognitionSVR0.268 ± 0.0940.236 ± 0.074+11.96%
SNP + FSRAVLT recognitionRidge regression0.263 ± 0.0610.238 ± 0.035+9.32%
SNP + FSRAVLT recognitionCNN0.304 ± 0.0650.270 ± 0.045+10.97%
SNP + VBMRAVLT totalSVR0.159 ± 0.0420.155 ± 0.035+2.52%
SNP + VBMRAVLT totalRidge regression0.166 ± 0.0320.159 ± 0.032+4.34%
SNP + VBMRAVLT totalCNN0.182 ± 0.0280.148 ± 0.037+18.88%
SNP + VBMRAVLT 30-minute recallSVR0.302 ± 0.0650.284 ± 0.084+5.95%
SNP + VBMRAVLT 30-minute recallRidge regression0.312 ± 0.0390.306 ± 0.061+2.05%
SNP + VBMRAVLT 30-minute recallCNN0.324 ± 0.0550.339 ± 0.079-4.79%
SNP + VBMRAVLT recognitionSVR0.300 ± 0.1030.303 ± 0.082-1.10%
SNP + VBMRAVLT recognitionRidge regression0.310 ± 0.0820.291 ± 0.094+5.97%
SNP + VBMRAVLT recognitionCNN0.387 ± 0.0910.296 ± 0.081+23.45%
SNPRAVLT totalSVR0.206 ± 0.0710.206 ± 0.065-0.10%
SNPRAVLT totalRidge regression0.218 ± 0.0650.208 ± 0.054+4.50%
SNPRAVLT totalCNN0.222 ± 0.0810.237 ± 0.058-6.77%
SNPRAVLT 30-minute recallSVR0.273 ± 0.0880.276 ± 0.091-0.84%
SNPRAVLT 30-minute recallRidge regression0.316 ± 0.0810.296 ± 0.084+6.17%
SNPRAVLT 30-minute recallCNN0.371 ± 0.0910.292 ± 0.090+21.25%
SNPRAVLT recognitionSVR0.390 ± 0.1240.390 ± 0.131-0.08%
SNPRAVLT recognitionRidge regression0.355 ± 0.1240.355 ± 0.111-0.03%
SNPRAVLT recognitionCNN0.408 ± 0.1120.401 ± 0.124+1.67%

Adapted from Seo, Brand & Wang (2024), Figure 3 ↗ · CC BY 4.0 · Inspect the original figure. Related research from Hua Wang’s lab; not a confirmed publication of my 2022 project.

How the model combines imaging and genetics
Longitudinal imaging–genetic enrichment
Related lab paper

A closer look at the factorization framework in Seo, Brand & Wang (2024), from the lab where I worked.

Longitudinal imaging–genetic enrichmentLongitudinal imagingXᵢ: d × nᵢGenetic measurementsX_SNP: d_SNP × nAvailable clinical scoresYₗ: c × lParticipant projectionszᵢ = Wᵢᵀ xᵢCommon representationG: shared participantsFixed-length featurespredict cognitive scores
Longitudinal projection

Participant-specific projections learn from different numbers of imaging visits; the final record becomes a fixed-length representation.

zᵢ = Wᵢᵀ xᵢ

Genetic structure

A group-sparsity penalty preserves relationships among SNPs, while factorization connects genetics to participant representations.

X_SNP ≈ H₀G

Shared factors

Imaging, genetics, and observed clinical scores share participant factors; the clinical term uses labeled participants.

Z ≈ H₁G; Yₗ ≈ H₂Gₗ

Prediction

Conventional prediction models use the enriched features. Trace-norm regularization couples the participant-specific projections.

variable-length histories → fixed-length zᵢ → clinical prediction

Source: Seo, Brand & Wang, 2024, Methods and Figure 2 ↗. This is related lab research, not a confirmed publication of my 2022 project.

Paper figures & project notes
Published multimodal imaging-genetics model from Hua Wang’s lab, Figure 2.View full size

Related lab research · Figure 2 from Seo, Brand & Wang (2024). A shared representation links imaging, genetic measurements, and clinical scores.

Seo, Brand & Wang (2024) · CC BY 4.0 · Unmodified · Original source ↗
Read the lab’s paper
05 / KUMAR BIOMATERIALS LAB · BIOSTATISTICSProject method

Flow-cytometry analysis

I built a Python pipeline to automate flow-cytometry gating and improve its objectivity and interpretability, working directly with Dr. Ramya Kumar.

My role: Biostatistics Research Fellow · February–August 2022

KUMAR LAB / THE GATING RULE I BUILT
Let the event counts define the gate

My approach divides a two-dimensional measurement space into checkerboard tiles and keeps events in tiles with enough neighbors. Adjust the grid and count threshold to see the gate change.

Simulated flow-cytometry events
3,200Input events27Removed by SD203Removed by tile count2,970Retained events

Swipe each plot sideways for the full axes.

01 / Input events
All 3200 simulated events. 27 excluded by the per-axis SD filter.0025025050050075075010001000FSC-A · simulated a.u.SSC-A · simulated a.u.3,200 input events
02 / Count the checkerboard
Checkerboard occupancy after SD filtering. Tile width 80; retain tiles with at least 15 events.0025025050050075075010001000FSC-A · simulated a.u.SSC-A · simulated a.u.Column 1, row 1: 7 events after SD filter; below threshold.Column 2, row 1: 23 events after SD filter; kept.Column 3, row 1: 3 events after SD filter; below threshold.Column 4, row 1: 0 events after SD filter; below threshold.Column 5, row 1: 0 events after SD filter; below threshold.Column 6, row 1: 0 events after SD filter; below threshold.Column 7, row 1: 0 events after SD filter; below threshold.Column 8, row 1: 1 events after SD filter; below threshold.Column 9, row 1: 1 events after SD filter; below threshold.Column 10, row 1: 2 events after SD filter; below threshold.Column 11, row 1: 2 events after SD filter; below threshold.Column 12, row 1: 0 events after SD filter; below threshold.Column 13, row 1: 0 events after SD filter; below threshold.Column 1, row 2: 31 events after SD filter; kept.Column 2, row 2: 231 events after SD filter; kept.Column 3, row 2: 111 events after SD filter; kept.Column 4, row 2: 4 events after SD filter; below threshold.Column 5, row 2: 3 events after SD filter; below threshold.Column 6, row 2: 1 events after SD filter; below threshold.Column 7, row 2: 1 events after SD filter; below threshold.Column 8, row 2: 0 events after SD filter; below threshold.Column 9, row 2: 0 events after SD filter; below threshold.Column 10, row 2: 1 events after SD filter; below threshold.Column 11, row 2: 1 events after SD filter; below threshold.Column 12, row 2: 0 events after SD filter; below threshold.Column 13, row 2: 0 events after SD filter; below threshold.Column 1, row 3: 5 events after SD filter; below threshold.Column 2, row 3: 67 events after SD filter; kept.Column 3, row 3: 61 events after SD filter; kept.Column 4, row 3: 10 events after SD filter; below threshold.Column 5, row 3: 15 events after SD filter; kept.Column 6, row 3: 11 events after SD filter; below threshold.Column 7, row 3: 3 events after SD filter; below threshold.Column 8, row 3: 1 events after SD filter; below threshold.Column 9, row 3: 1 events after SD filter; below threshold.Column 10, row 3: 1 events after SD filter; below threshold.Column 11, row 3: 1 events after SD filter; below threshold.Column 12, row 3: 0 events after SD filter; below threshold.Column 13, row 3: 0 events after SD filter; below threshold.Column 1, row 4: 0 events after SD filter; below threshold.Column 2, row 4: 1 events after SD filter; below threshold.Column 3, row 4: 4 events after SD filter; below threshold.Column 4, row 4: 23 events after SD filter; kept.Column 5, row 4: 73 events after SD filter; kept.Column 6, row 4: 77 events after SD filter; kept.Column 7, row 4: 29 events after SD filter; kept.Column 8, row 4: 0 events after SD filter; below threshold.Column 9, row 4: 0 events after SD filter; below threshold.Column 10, row 4: 0 events after SD filter; below threshold.Column 11, row 4: 1 events after SD filter; below threshold.Column 12, row 4: 0 events after SD filter; below threshold.Column 13, row 4: 0 events after SD filter; below threshold.Column 1, row 5: 0 events after SD filter; below threshold.Column 2, row 5: 0 events after SD filter; below threshold.Column 3, row 5: 0 events after SD filter; below threshold.Column 4, row 5: 13 events after SD filter; below threshold.Column 5, row 5: 124 events after SD filter; kept.Column 6, row 5: 300 events after SD filter; kept.Column 7, row 5: 148 events after SD filter; kept.Column 8, row 5: 16 events after SD filter; kept.Column 9, row 5: 1 events after SD filter; below threshold.Column 10, row 5: 1 events after SD filter; below threshold.Column 11, row 5: 0 events after SD filter; below threshold.Column 12, row 5: 0 events after SD filter; below threshold.Column 13, row 5: 0 events after SD filter; below threshold.Column 1, row 6: 0 events after SD filter; below threshold.Column 2, row 6: 1 events after SD filter; below threshold.Column 3, row 6: 1 events after SD filter; below threshold.Column 4, row 6: 14 events after SD filter; below threshold.Column 5, row 6: 97 events after SD filter; kept.Column 6, row 6: 283 events after SD filter; kept.Column 7, row 6: 263 events after SD filter; kept.Column 8, row 6: 57 events after SD filter; kept.Column 9, row 6: 6 events after SD filter; below threshold.Column 10, row 6: 2 events after SD filter; below threshold.Column 11, row 6: 0 events after SD filter; below threshold.Column 12, row 6: 0 events after SD filter; below threshold.Column 13, row 6: 0 events after SD filter; below threshold.Column 1, row 7: 1 events after SD filter; below threshold.Column 2, row 7: 1 events after SD filter; below threshold.Column 3, row 7: 1 events after SD filter; below threshold.Column 4, row 7: 0 events after SD filter; below threshold.Column 5, row 7: 23 events after SD filter; kept.Column 6, row 7: 159 events after SD filter; kept.Column 7, row 7: 243 events after SD filter; kept.Column 8, row 7: 91 events after SD filter; kept.Column 9, row 7: 5 events after SD filter; below threshold.Column 10, row 7: 3 events after SD filter; below threshold.Column 11, row 7: 0 events after SD filter; below threshold.Column 12, row 7: 0 events after SD filter; below threshold.Column 13, row 7: 0 events after SD filter; below threshold.Column 1, row 8: 1 events after SD filter; below threshold.Column 2, row 8: 1 events after SD filter; below threshold.Column 3, row 8: 1 events after SD filter; below threshold.Column 4, row 8: 0 events after SD filter; below threshold.Column 5, row 8: 3 events after SD filter; below threshold.Column 6, row 8: 31 events after SD filter; kept.Column 7, row 8: 90 events after SD filter; kept.Column 8, row 8: 62 events after SD filter; kept.Column 9, row 8: 15 events after SD filter; kept.Column 10, row 8: 3 events after SD filter; below threshold.Column 11, row 8: 2 events after SD filter; below threshold.Column 12, row 8: 0 events after SD filter; below threshold.Column 13, row 8: 0 events after SD filter; below threshold.Column 1, row 9: 0 events after SD filter; below threshold.Column 2, row 9: 0 events after SD filter; below threshold.Column 3, row 9: 1 events after SD filter; below threshold.Column 4, row 9: 0 events after SD filter; below threshold.Column 5, row 9: 2 events after SD filter; below threshold.Column 6, row 9: 0 events after SD filter; below threshold.Column 7, row 9: 10 events after SD filter; below threshold.Column 8, row 9: 13 events after SD filter; below threshold.Column 9, row 9: 13 events after SD filter; below threshold.Column 10, row 9: 57 events after SD filter; kept.Column 11, row 9: 13 events after SD filter; below threshold.Column 12, row 9: 0 events after SD filter; below threshold.Column 13, row 9: 0 events after SD filter; below threshold.Column 1, row 10: 1 events after SD filter; below threshold.Column 2, row 10: 2 events after SD filter; below threshold.Column 3, row 10: 2 events after SD filter; below threshold.Column 4, row 10: 0 events after SD filter; below threshold.Column 5, row 10: 0 events after SD filter; below threshold.Column 6, row 10: 0 events after SD filter; below threshold.Column 7, row 10: 1 events after SD filter; below threshold.Column 8, row 10: 2 events after SD filter; below threshold.Column 9, row 10: 26 events after SD filter; kept.Column 10, row 10: 104 events after SD filter; kept.Column 11, row 10: 19 events after SD filter; kept.Column 12, row 10: 0 events after SD filter; below threshold.Column 13, row 10: 0 events after SD filter; below threshold.Column 1, row 11: 0 events after SD filter; below threshold.Column 2, row 11: 1 events after SD filter; below threshold.Column 3, row 11: 1 events after SD filter; below threshold.Column 4, row 11: 2 events after SD filter; below threshold.Column 5, row 11: 0 events after SD filter; below threshold.Column 6, row 11: 0 events after SD filter; below threshold.Column 7, row 11: 1 events after SD filter; below threshold.Column 8, row 11: 1 events after SD filter; below threshold.Column 9, row 11: 6 events after SD filter; below threshold.Column 10, row 11: 21 events after SD filter; kept.Column 11, row 11: 4 events after SD filter; below threshold.Column 12, row 11: 0 events after SD filter; below threshold.Column 13, row 11: 0 events after SD filter; below threshold.Column 1, row 12: 0 events after SD filter; below threshold.Column 2, row 12: 0 events after SD filter; below threshold.Column 3, row 12: 0 events after SD filter; below threshold.Column 4, row 12: 0 events after SD filter; below threshold.Column 5, row 12: 0 events after SD filter; below threshold.Column 6, row 12: 0 events after SD filter; below threshold.Column 7, row 12: 0 events after SD filter; below threshold.Column 8, row 12: 0 events after SD filter; below threshold.Column 9, row 12: 0 events after SD filter; below threshold.Column 10, row 12: 0 events after SD filter; below threshold.Column 11, row 12: 0 events after SD filter; below threshold.Column 12, row 12: 0 events after SD filter; below threshold.Column 13, row 12: 0 events after SD filter; below threshold.Column 1, row 13: 0 events after SD filter; below threshold.Column 2, row 13: 0 events after SD filter; below threshold.Column 3, row 13: 0 events after SD filter; below threshold.Column 4, row 13: 0 events after SD filter; below threshold.Column 5, row 13: 0 events after SD filter; below threshold.Column 6, row 13: 0 events after SD filter; below threshold.Column 7, row 13: 0 events after SD filter; below threshold.Column 8, row 13: 0 events after SD filter; below threshold.Column 9, row 13: 0 events after SD filter; below threshold.Column 10, row 13: 0 events after SD filter; below threshold.Column 11, row 13: 0 events after SD filter; below threshold.Column 12, row 13: 0 events after SD filter; below threshold.Column 13, row 13: 0 events after SD filter; below threshold.13 × 13 tiles · 32 pass
03 / Keep qualifying events
2970 retained simulated events after both gates.0025025050050075075010001000FSC-A · simulated a.u.SSC-A · simulated a.u.2,970 kept · 92.8%
Within SD boundsExcluded tailRetained event / qualifying tileTile shading: log-scaled event count

Tile (6, 6) · FSC-A 400–480, SSC-A 400–480 a.u. 283 input events → 283 after the SD filter → 283 retained. This tile passes the ≥ 15-event rule.

How the gate is calculated

The demo uses fixed, seeded synthetic forward-scatter and side-scatter measurements on a linear 0–1000 arbitrary-unit scale. Points represent events, not verified single live cells. No patient or experimental records are used.

  1. Calculate each axis’s mean and population SD once from all input events.
  2. If tail filtering is enabled, reject an event if either axis falls outside mean ± k SD. Equality is kept. This is a single pass, not iterative clipping.
  3. Anchor the grid at (0, 0). Count surviving events in each square. Tile intervals include their lower edge and exclude their upper edge; the final interval includes 1000.
  4. Keep every surviving event in a tile whose count is at least the chosen minimum.

This is an interactive implementation of my method description, not a reproduction of an archived pipeline or a validated live-cell/singlet gate. Dense debris can remain, and sparse biological populations can be excluded. Tile size and minimum occupancy must be considered together.

Fixed input statistics: FSC-A mean 440.33, SD 176.76; SSC-A mean 413.45, SD 179.59. Tile width 80 a.u.; count threshold 15; tail cutoff 2.5 SD.

Counts at the current settings
StepEvents removedEvents remaining
Input03200
SD filter273173
Minimum tile count2032970

Method: my account of the Kumar Lab project. Research context: Mines SURF 2022. Implementation choices for this demo are listed above; simulated values are not research results.

Project workflow and source details
Automated analysis for polymeric gene delivery
SURF 2022 project

My Kumar Lab project replaced a manual analysis task with a Python pipeline. Select a stage to see its role.

Automated analysis for polymeric gene deliveryFlow-cytometry eventscell-level measurementsAutomated gatingmathematical + statistical rulesPopulation summariesobjective, interpretable output
Measurements

Flow cytometry provides measurements for individual events in polymeric gene-delivery experiments.

event × measurement matrix

Gating

I developed mathematical and statistical methods to automate population selection and improve its objectivity.

measurements → gating rule → selected population

Interpretation

The pipeline was designed to make the selection process and its output interpretable. I was the sole programmer, working with Dr. Ramya Kumar.

selected population → reproducible analysis

The interactive checkerboard above implements my description of the method with fixed simulated events. Its grid origin, SD calculation, and rule order are explicit demo choices; it does not reproduce an archived pipeline.

Lab references & project notes
Kumar Biomaterials Lab illustration of polymers, biomolecules, and cellular structures.View full size

Original lab illustration · Polymer discovery, the broader research setting for my flow-cytometry analysis work.

© Kumar Biomaterials Lab · Unmodified · Original source ↗
See the SURF project listing
06 / FARNSWORTH LAB · TYPE 1 DIABETESCoauthored research

Targeted delivery to pancreatic β-cells

I studied extracellular-matrix effects on cell differentiation and insulin-secreting cell viability, and worked on targeted nanocapsule delivery and image analysis. I’m a coauthor of the 2024 research abstract on polycaprolactone nanocapsules for pancreatic β-cell survival.

My role: Type 1 Diabetes Researcher · August 2023–May 2024

FARNSWORTH LAB / CELL ENVIRONMENT + TARGETED DELIVERY
Extracellular matrix and β-cell-targeted delivery

I studied extracellular-matrix effects on cell differentiation and insulin-secreting cell viability, alongside targeted nanocapsules. These diagrams explain the two research directions.

01 / EXTRACELLULAR MATRIX
How a cell responds to its surroundings

The extracellular matrix provides a physical scaffold and molecular contacts. Explore the path from the environment outside a cell to changes in its state.

Swipe diagrams sideways to inspect their labels.

Conceptual extracellular-matrix scaffold, adhesion receptors, intracellular signaling, and cell-state readouts.Extracellular scaffoldPhysical support + molecular cuesCell–matrix contactAdhesion → signaling → nucleusA conceptual signaling routeCell-state readoutsDifferentiation / cell identityFunction / insulin secretionViability / survivalNo measured response values

The extracellular matrix surrounds cells and offers physical and molecular cues. This sketch shows a generic scaffold; it does not assign a particular material or stiffness to my experiment.

Conceptual diagram, not a measured differentiation time course. The specific cell lineage and matrix formulation are not assigned here. The lab’s published research includes ECM-containing scaffolds for islet function and survival.

02 / TARGETED NANOCAPSULES
Follow a capsule to a β-cell

A polymer shell carries the cargo. A surface coating provides a molecular targeting cue. Follow one capsule from formulation to cell-associated delivery.

Illustrative animation · reported formulations
Illustrative Anti-ENTPD3 antibody-coated PCL nanocapsule carrying Cy5 tracer toward a beta cell. Motion and intracellular release are schematic.Coated PCL nanocapsuleSingle-particle illustration · not to scaleNucleusPancreatic β-cellENTPD3Cell-associated cargoAnti-ENTPD3 antibodySurface targeting cueCy5 tracerEncapsulated cargoUptake / release schematic
Encapsulate the cargo

The reported formulation encloses Cy5 tracer in a polycaprolactone (PCL) nanocapsule. Cy5 is the fluorescent tracer used to examine delivery; it is not the therapeutic peptide.

PCL shellTargeting coatingCargoCell-surface target

Motion, timing, sizes, and the intracellular release sequence are illustrative. The animation does not predict targeting efficiency, drug dose, or cell survival. The study measured targeting, uptake, and viability; this is not a resolved uptake mechanism.

Nanocapsule formulations: Akolade, Collins, Fremin, Muhr & Farnsworth, 2024 research abstract, PDF p. 481. Matrix research context: Farnsworth Lab research. My ECM/differentiation contribution is described from my experience; the diagram does not assign it to an unconfirmed publication.

Formulations and experimental readouts
Targeted polycaprolactone nanocapsules
Coauthored research abstract

The formulation and experiments described in the 2024 research abstract I coauthored with the Farnsworth Lab.

Targeted polycaprolactone nanocapsulesPCL capsuleencapsulated cargoCargoCy5 · δV1-1 · TAT–δV1-1HA–Exendin-4 coatingGLP-1 receptor agonistENTPD3 antibody coatinghuman β-cell markerMouse / human isletswith and without cytokinesNOD micein vivo targeting
Cargo

Cy5, δV1-1, or TAT-conjugated δV1-1 was encapsulated in polycaprolactone using emulsification and solvent evaporation.

PCL + cargo → nanocapsules

HA–Exendin-4

One coating combined hyaluronic acid with the GLP-1 receptor agonist Exendin-4.

HA–Ex4 → β-cell-directed formulation

ENTPD3 antibody

The other coating targeted ENTPD3, a human β-cell marker. The abstract reports more than 70% delivery to insulin-positive β-cells for this formulation.

ENTPD3 antibody → insulin-positive β-cells

Experimental readouts

The study evaluated uptake and survival in isolated mouse and human islets, and targeting in NOD mice.
targeting / uptake + cytokine-associated viability

Akolade, Collins, Fremin, Muhr & Farnsworth · 2024 abstract, PDF page 481 ↗. The diagram represents the reported formulation and study design, not a simulated response curve.

Lab references & project notes
Published graphical abstract from Collins and Farnsworth on targeted nanocarriers for pancreatic beta cells.View full size

Related lab review · The publicly displayed graphical abstract on beta-cell-targeted nanocarriers.

Collins & Farnsworth (2025) · Diabetologia · Unmodified · Original source ↗

More about my experience and education

Explore my background
04 / NEW RESEARCH POSITION

Hinda and Arthur Marcus Institute for Aging Research

Harvard Medical School

Sehgal Lab

To be announced soon

I’ve joined Raghav Sehgal at the Marcus Institute. More about the research soon.

Research figure

Scroll to inspect the original figure. Open image in a new tab ↗